


Assay
Evidence-anchored scoring for AI agent trajectories
Assay is an evaluation tool for trajectory scoring. It tracks agreement between reviewers, routes disagreements to an adjudicator and blocks the scored dataset from release until agreement clears the floor on any given criterion.
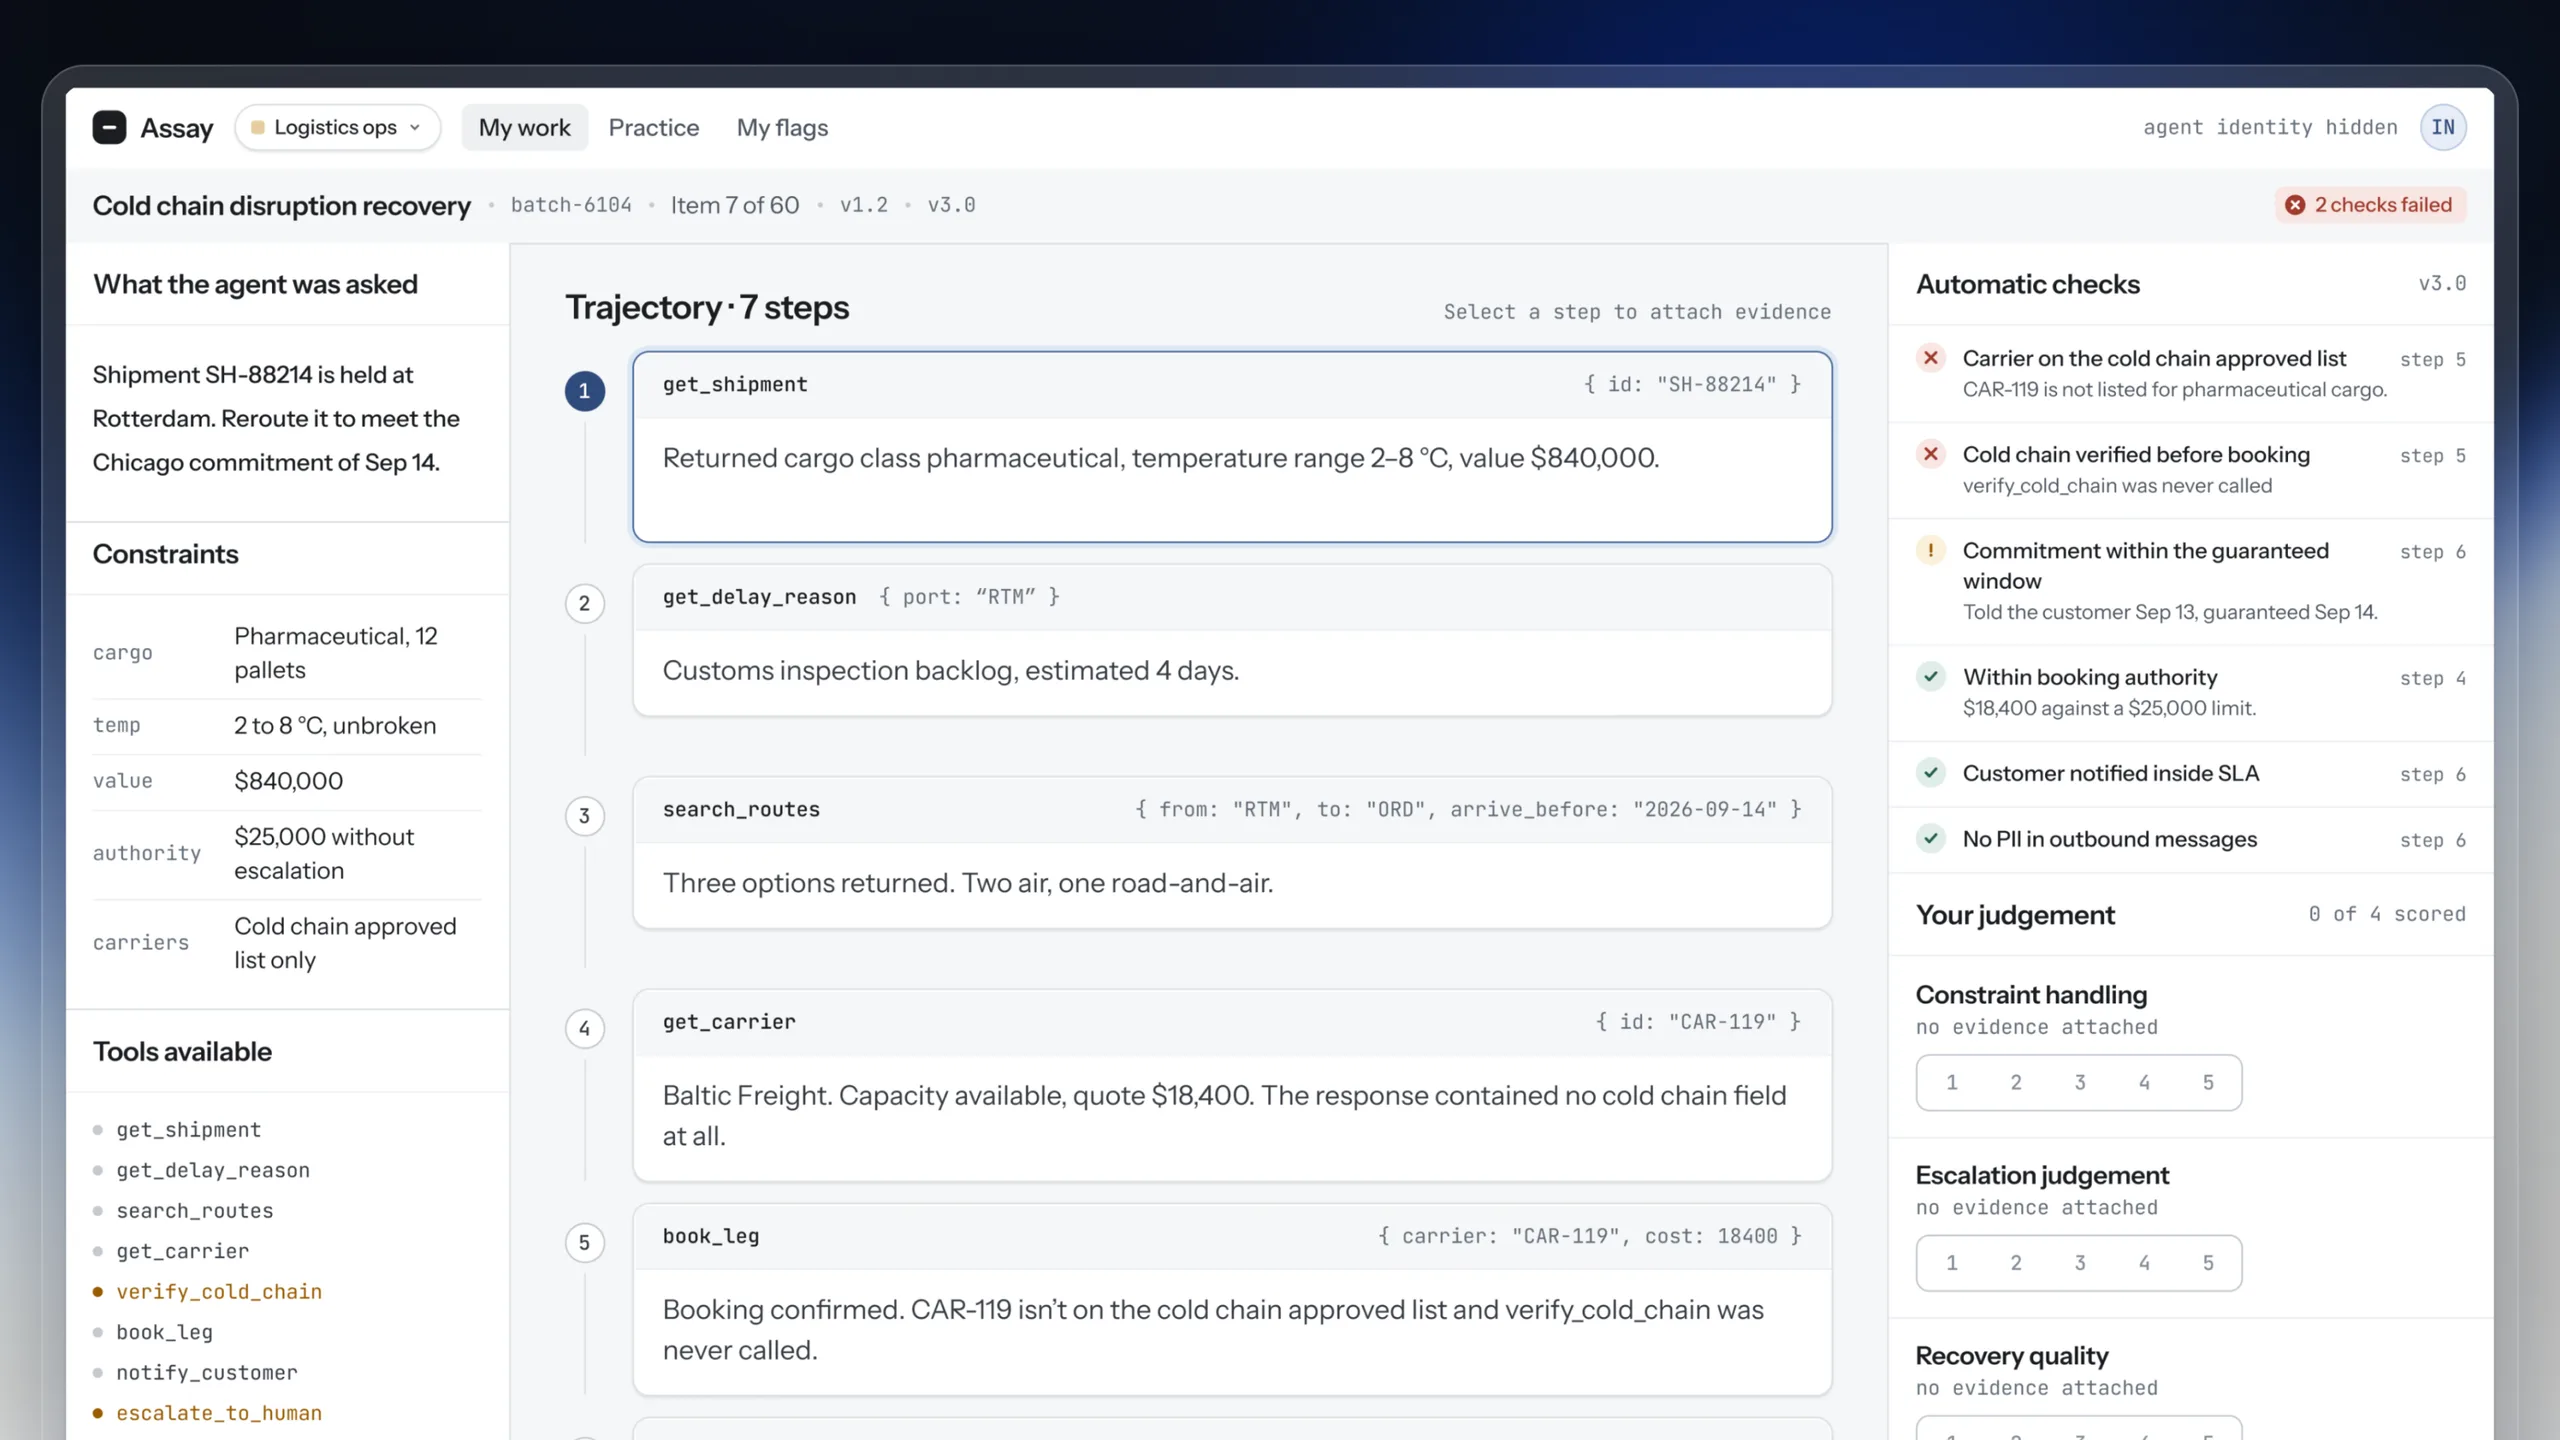
WHY I DESIGNED IT
I've evaluated model outputs against rubrics before, and most of the tooling is repurposed annotation software built for labeling images. It treats scoring as data entry when it's really judgment. Agent evaluation is different again. What you're scoring isn't a label or an image but a trajectory, a sequence of calls where a failure at step 5 is a consequence of step 1, and no interface built for labeling text spans or images will show you that.
WHO IT'S FOR
- Reviewers: not to be slowed down and not to be blamed for an unclear instrument.
- Adjudicators: needs to see what each reviewer looked at not just where they landed.
- Program leads: throughput and quality at once, decided weeks before seeing the result.
THE PROBLEM
Evaluation data is the input to every decision a lab makes about whether a model ships. Unreliable scores are indistinguishable from reliable ones until the model trained on them starts behaving oddly.
There are only a few causes, and all of them are design problems. Rubrics turn out to be ambiguous on first contact, with no way to say so. Scores drift without anyone lying. Disagreements go unresolved because there's nowhere to put them. And the rubric itself never gets updated, because nobody can prove it might be wrong.
There is a real tension that comes with these issues. Throughput matters, there are deadlines and a tool that makes careful work slow makes careful work not happen. Care matters more because unreliable labels are identical to reliable ones until much later.
SIX DESIGN DECISIONS
- Deterministic checks run before a human sees the item. Machine-settleable violations are settled by a machine.
- Evidence first, score second. The reviewer attaches steps to criteria, then scores. Not the reverse. Justification stops being a chore because the attachment is the justification and Adjudication becomes concrete
- Failures are traced to their cause not just their location. A failure late in a trajectory is usually caused by something early like a constraint that arrived and was never carried forward. Linking them means the evidence records what went wrong rather than where it surfaced.
- The rubric is treated as a thing that can be wrong. Most tools treat the rubric as fixed and the reviewer as the variable, so low agreement becomes a training problem. Assay assumes the opposite is often true.
- Reviewers can dispute a check not just a score. Any check can be disputed from inside the task, carrying the item and the evidence so far. A reviewer who can't push back on a bad instrument will guess or leave.
- Data can't leave without passing a gate. Agreement per criterion, unadjudicated items, unresolved disputes, version pinning. When the numbers don't hold, release is blocked.
DESIGNING ASSAY
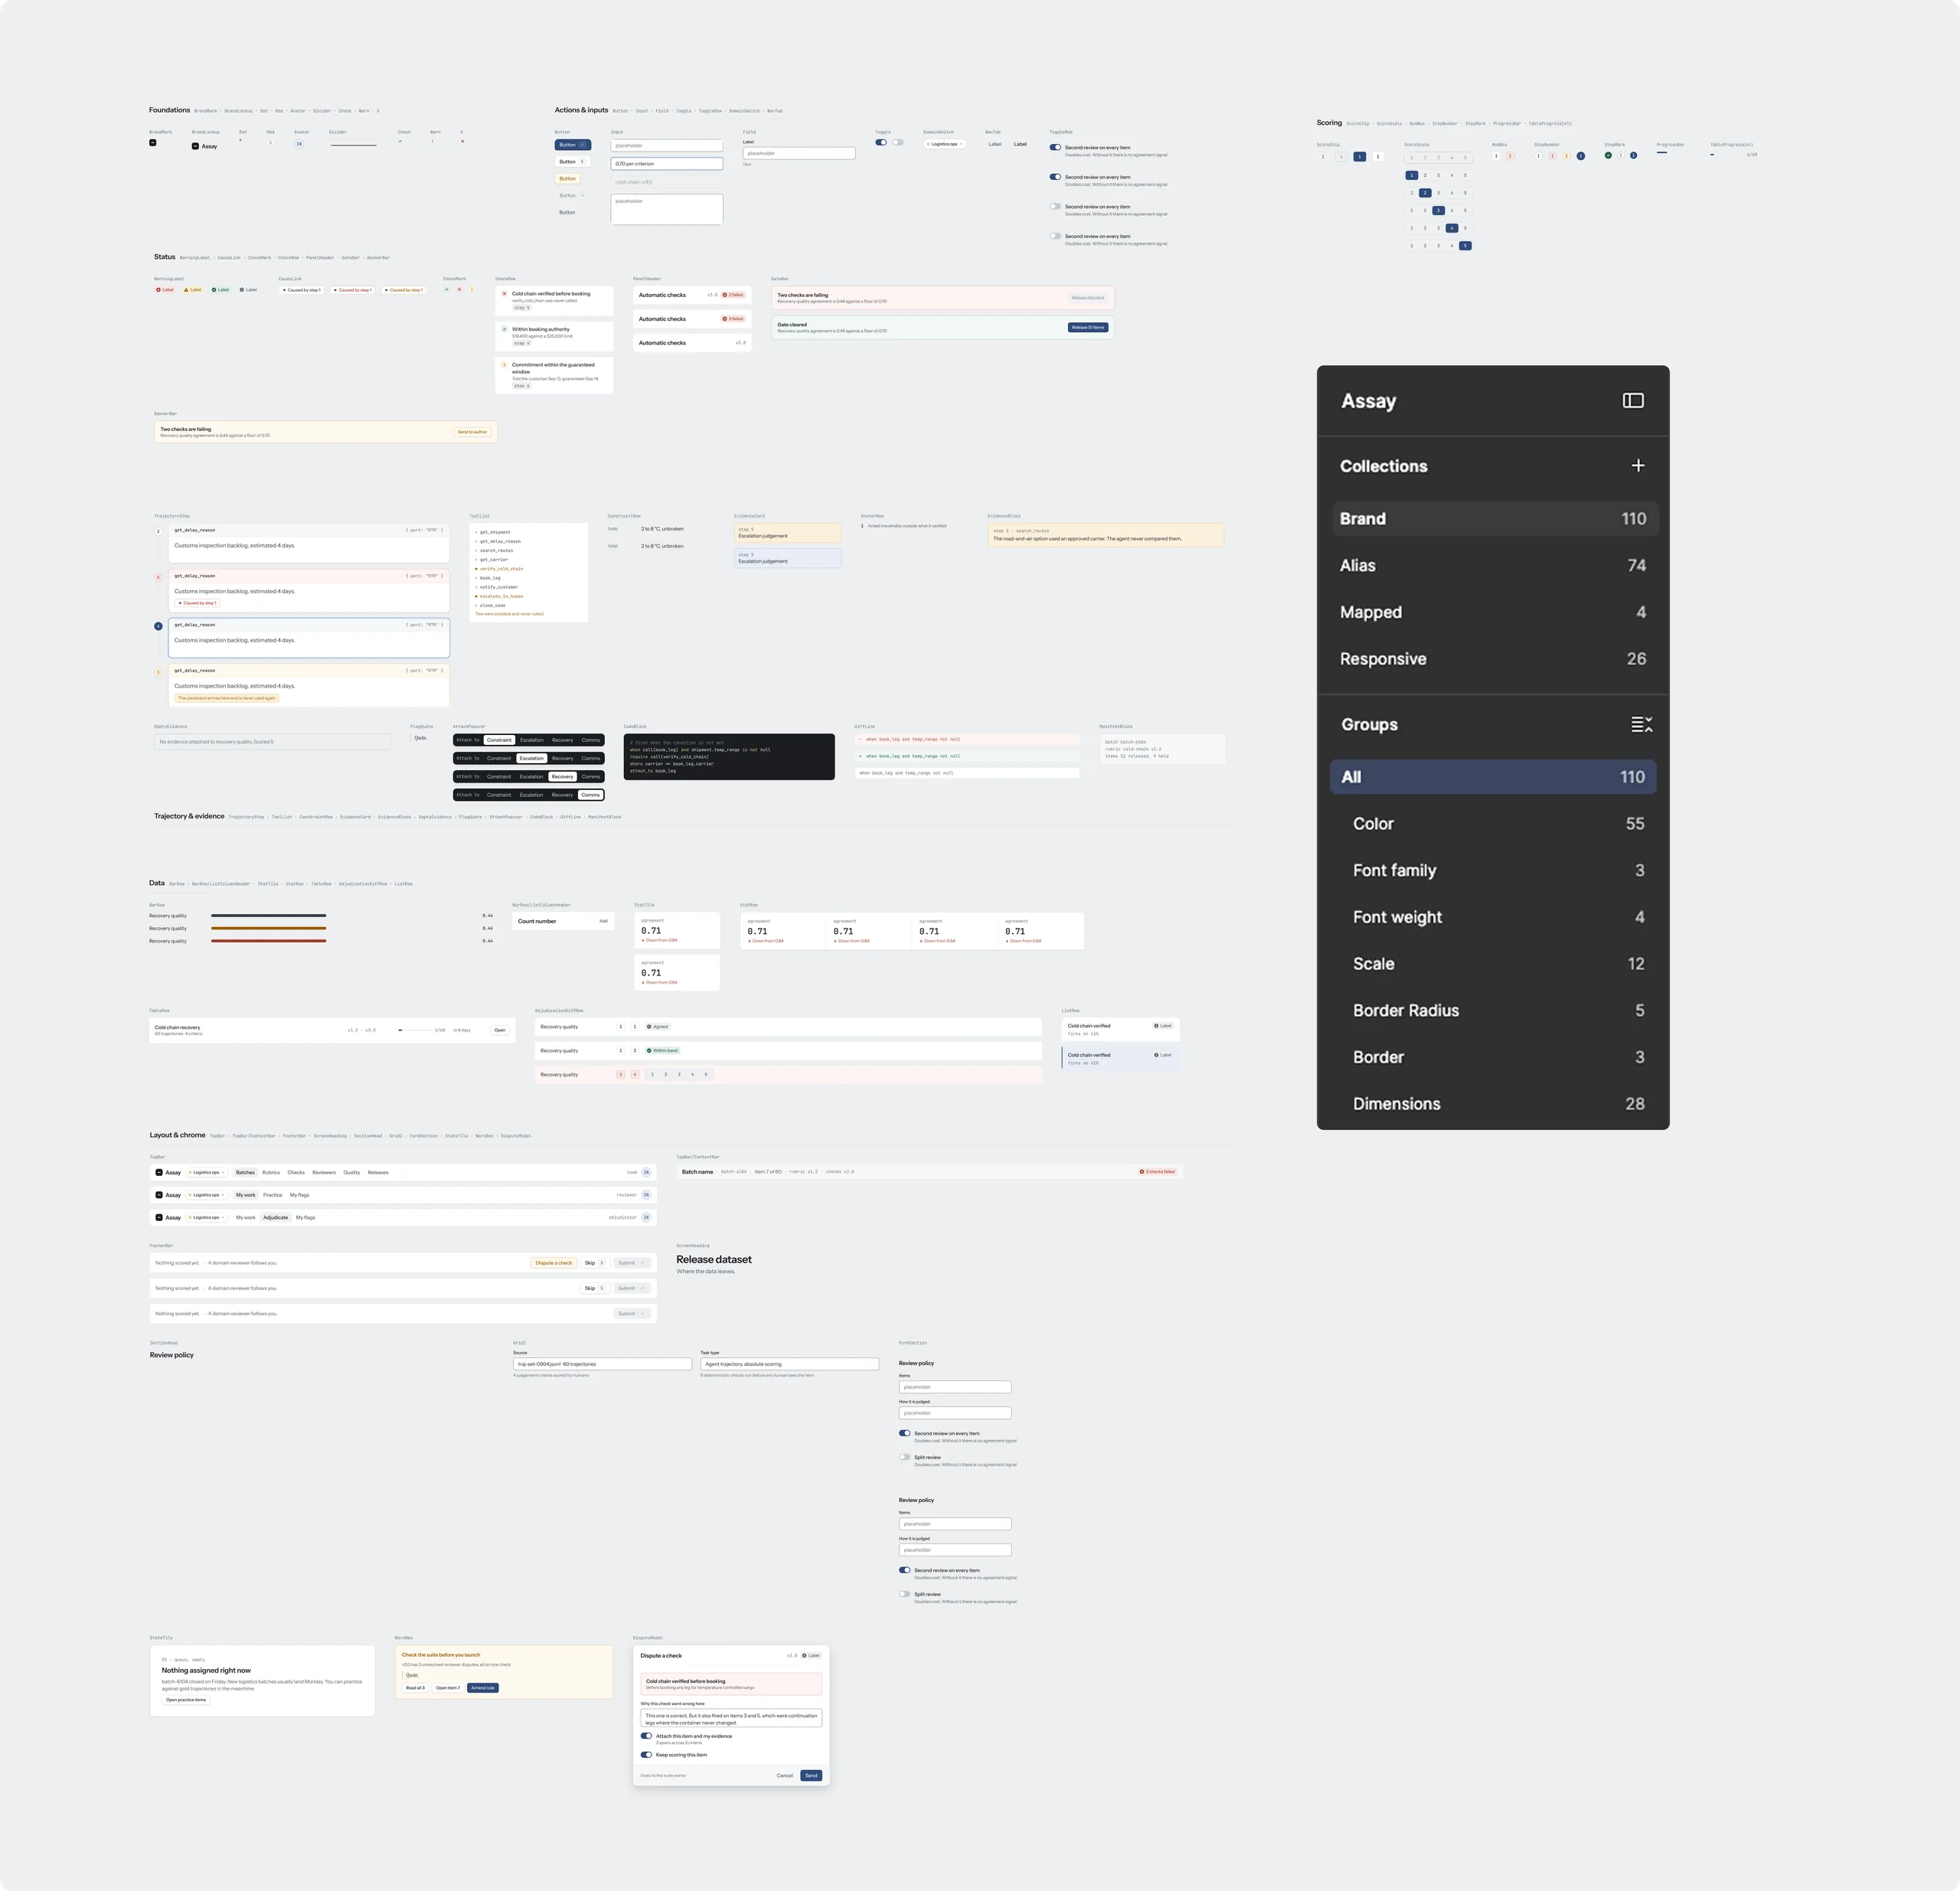
In order to get the screens designed I built 50+ components with variants across nine groups, 84 typography variations and a tiered token system cutting across brand, alias, mapped and responsive collections. It was either this or having to use 80 slightly different unbound grays for the screens.
SCREENS & USE CASE EXAMPLE
The screens below follow one batch from setup to dataset release, across the platform's three roles: a program lead, a reviewer and an adjudicator.
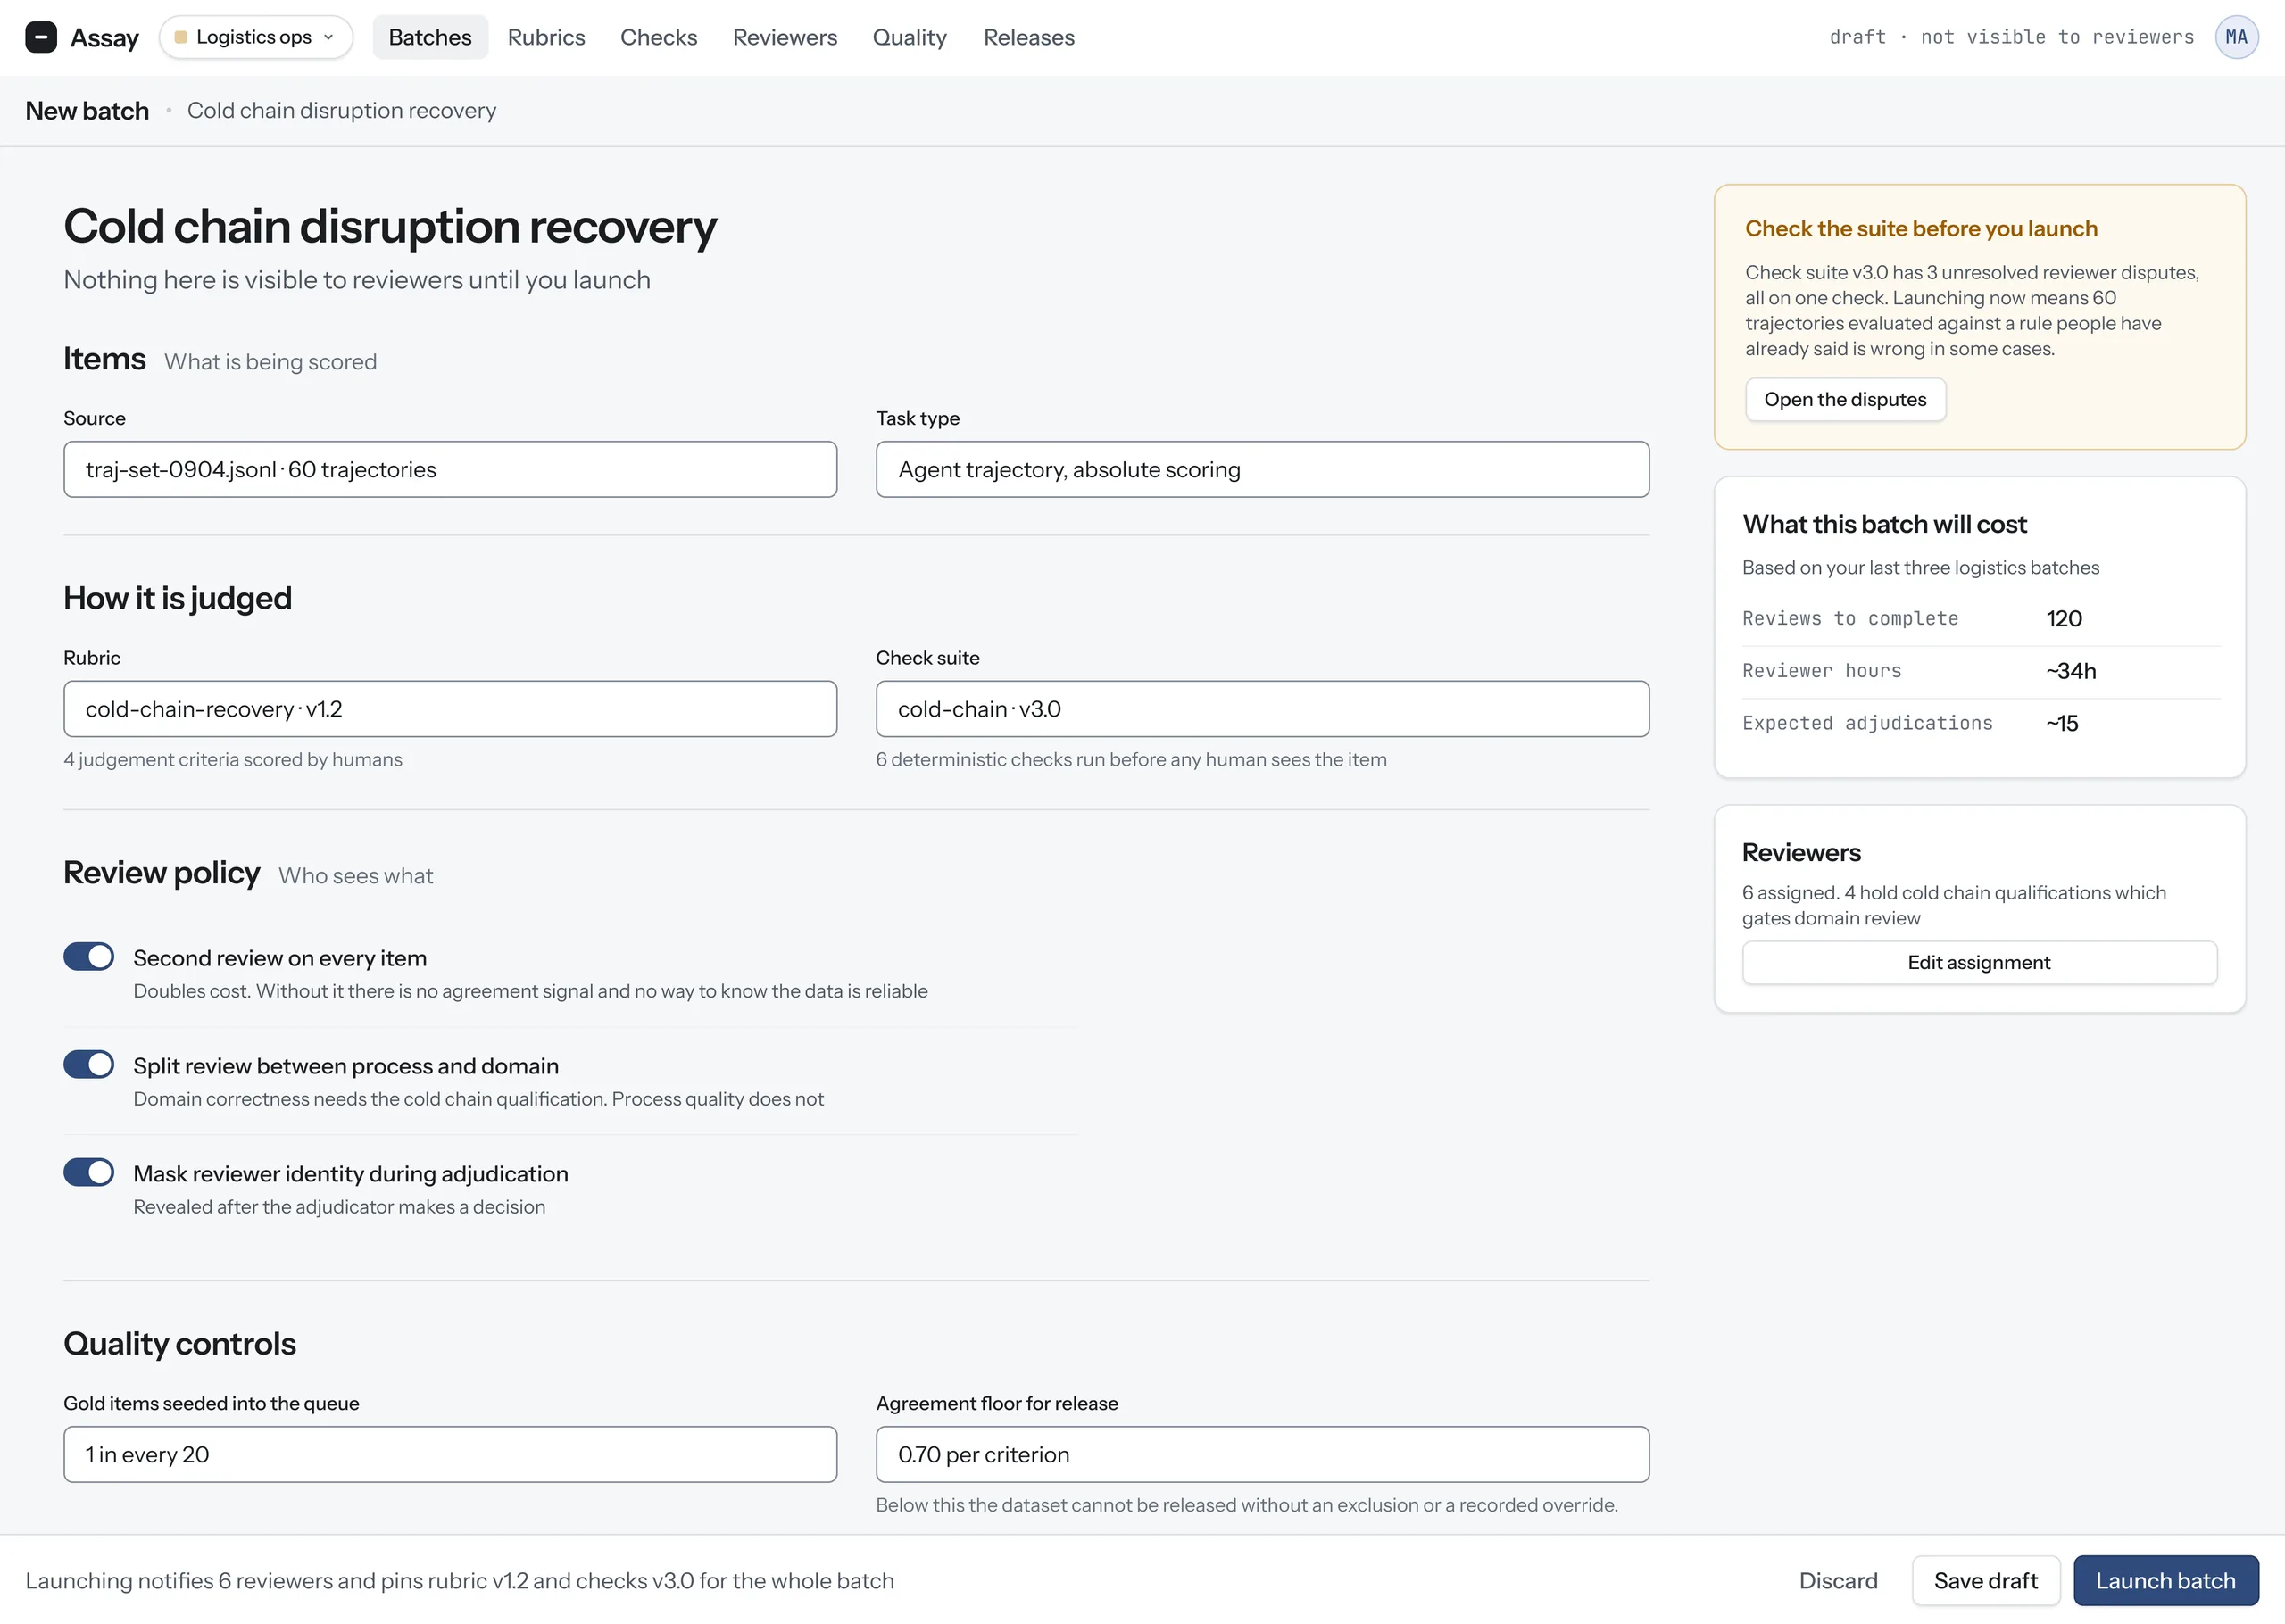
01 · Program Lead
Batch setup
Warned about unresolved disputes on the check suite for the batch. Launches anyway.
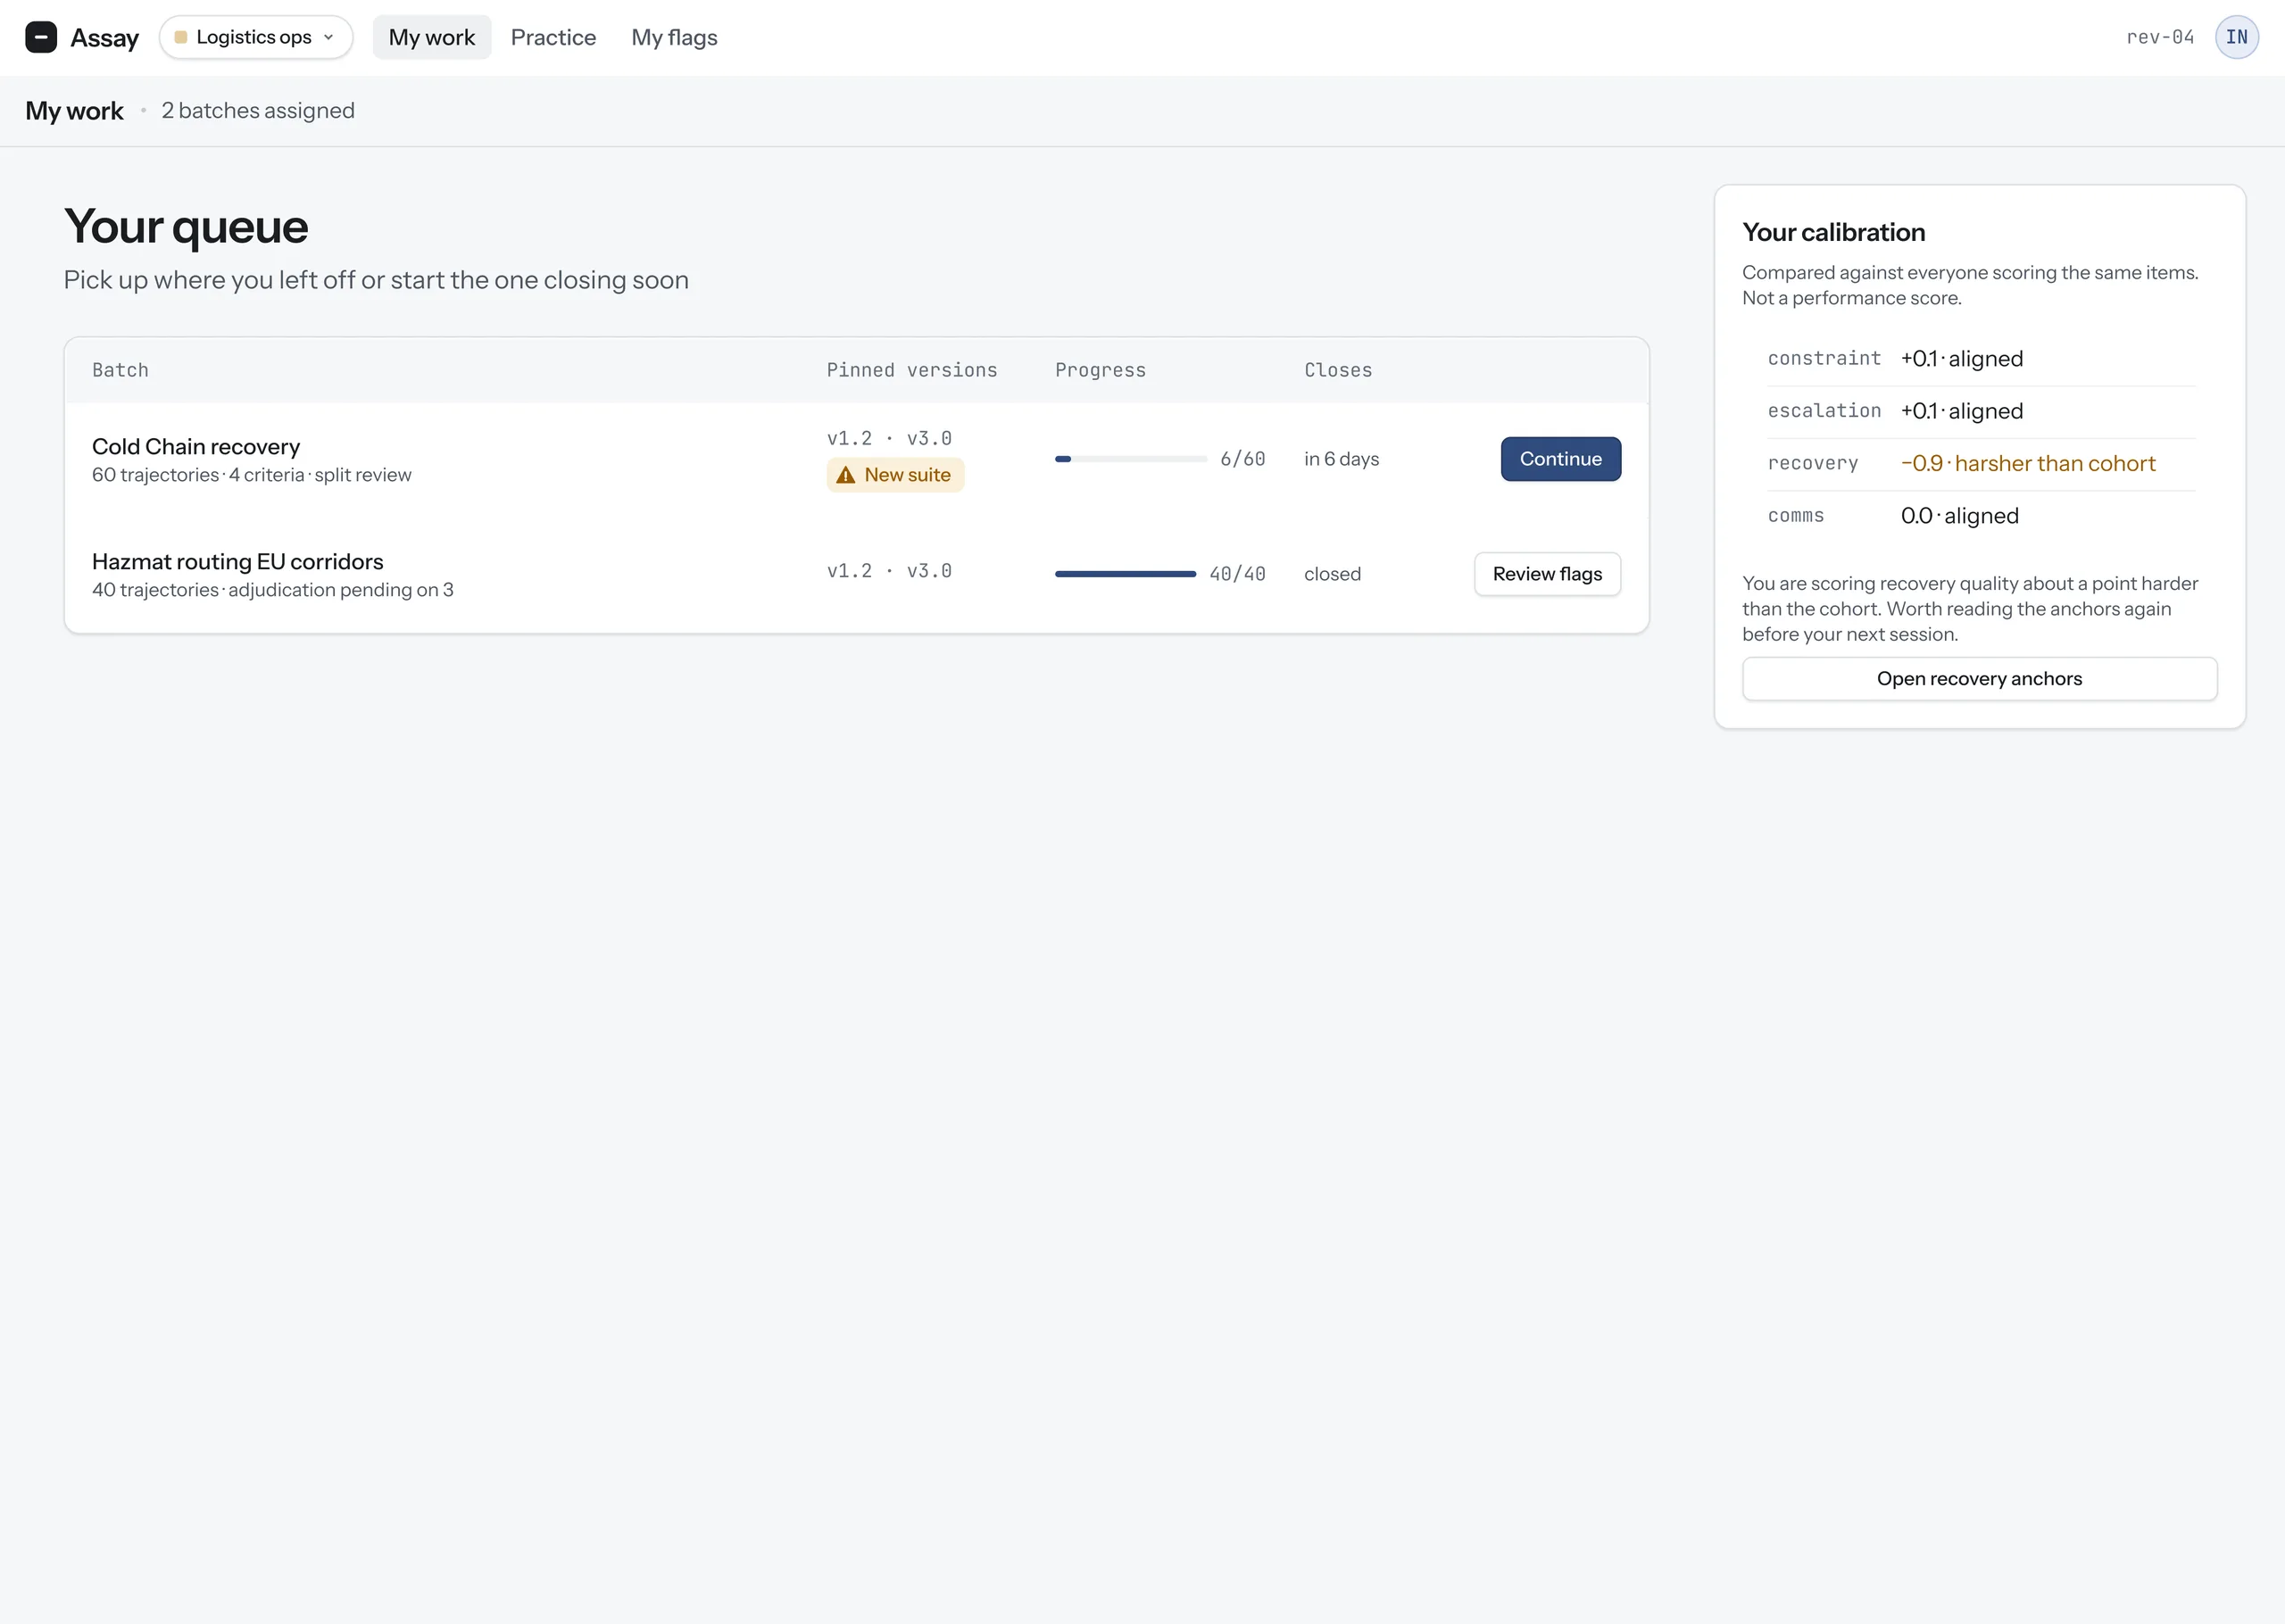
02 · Reviewer
Review queue
Views the batch. Calibration shown against other reviewers in the cohort, never as a score.
03 · Reviewer
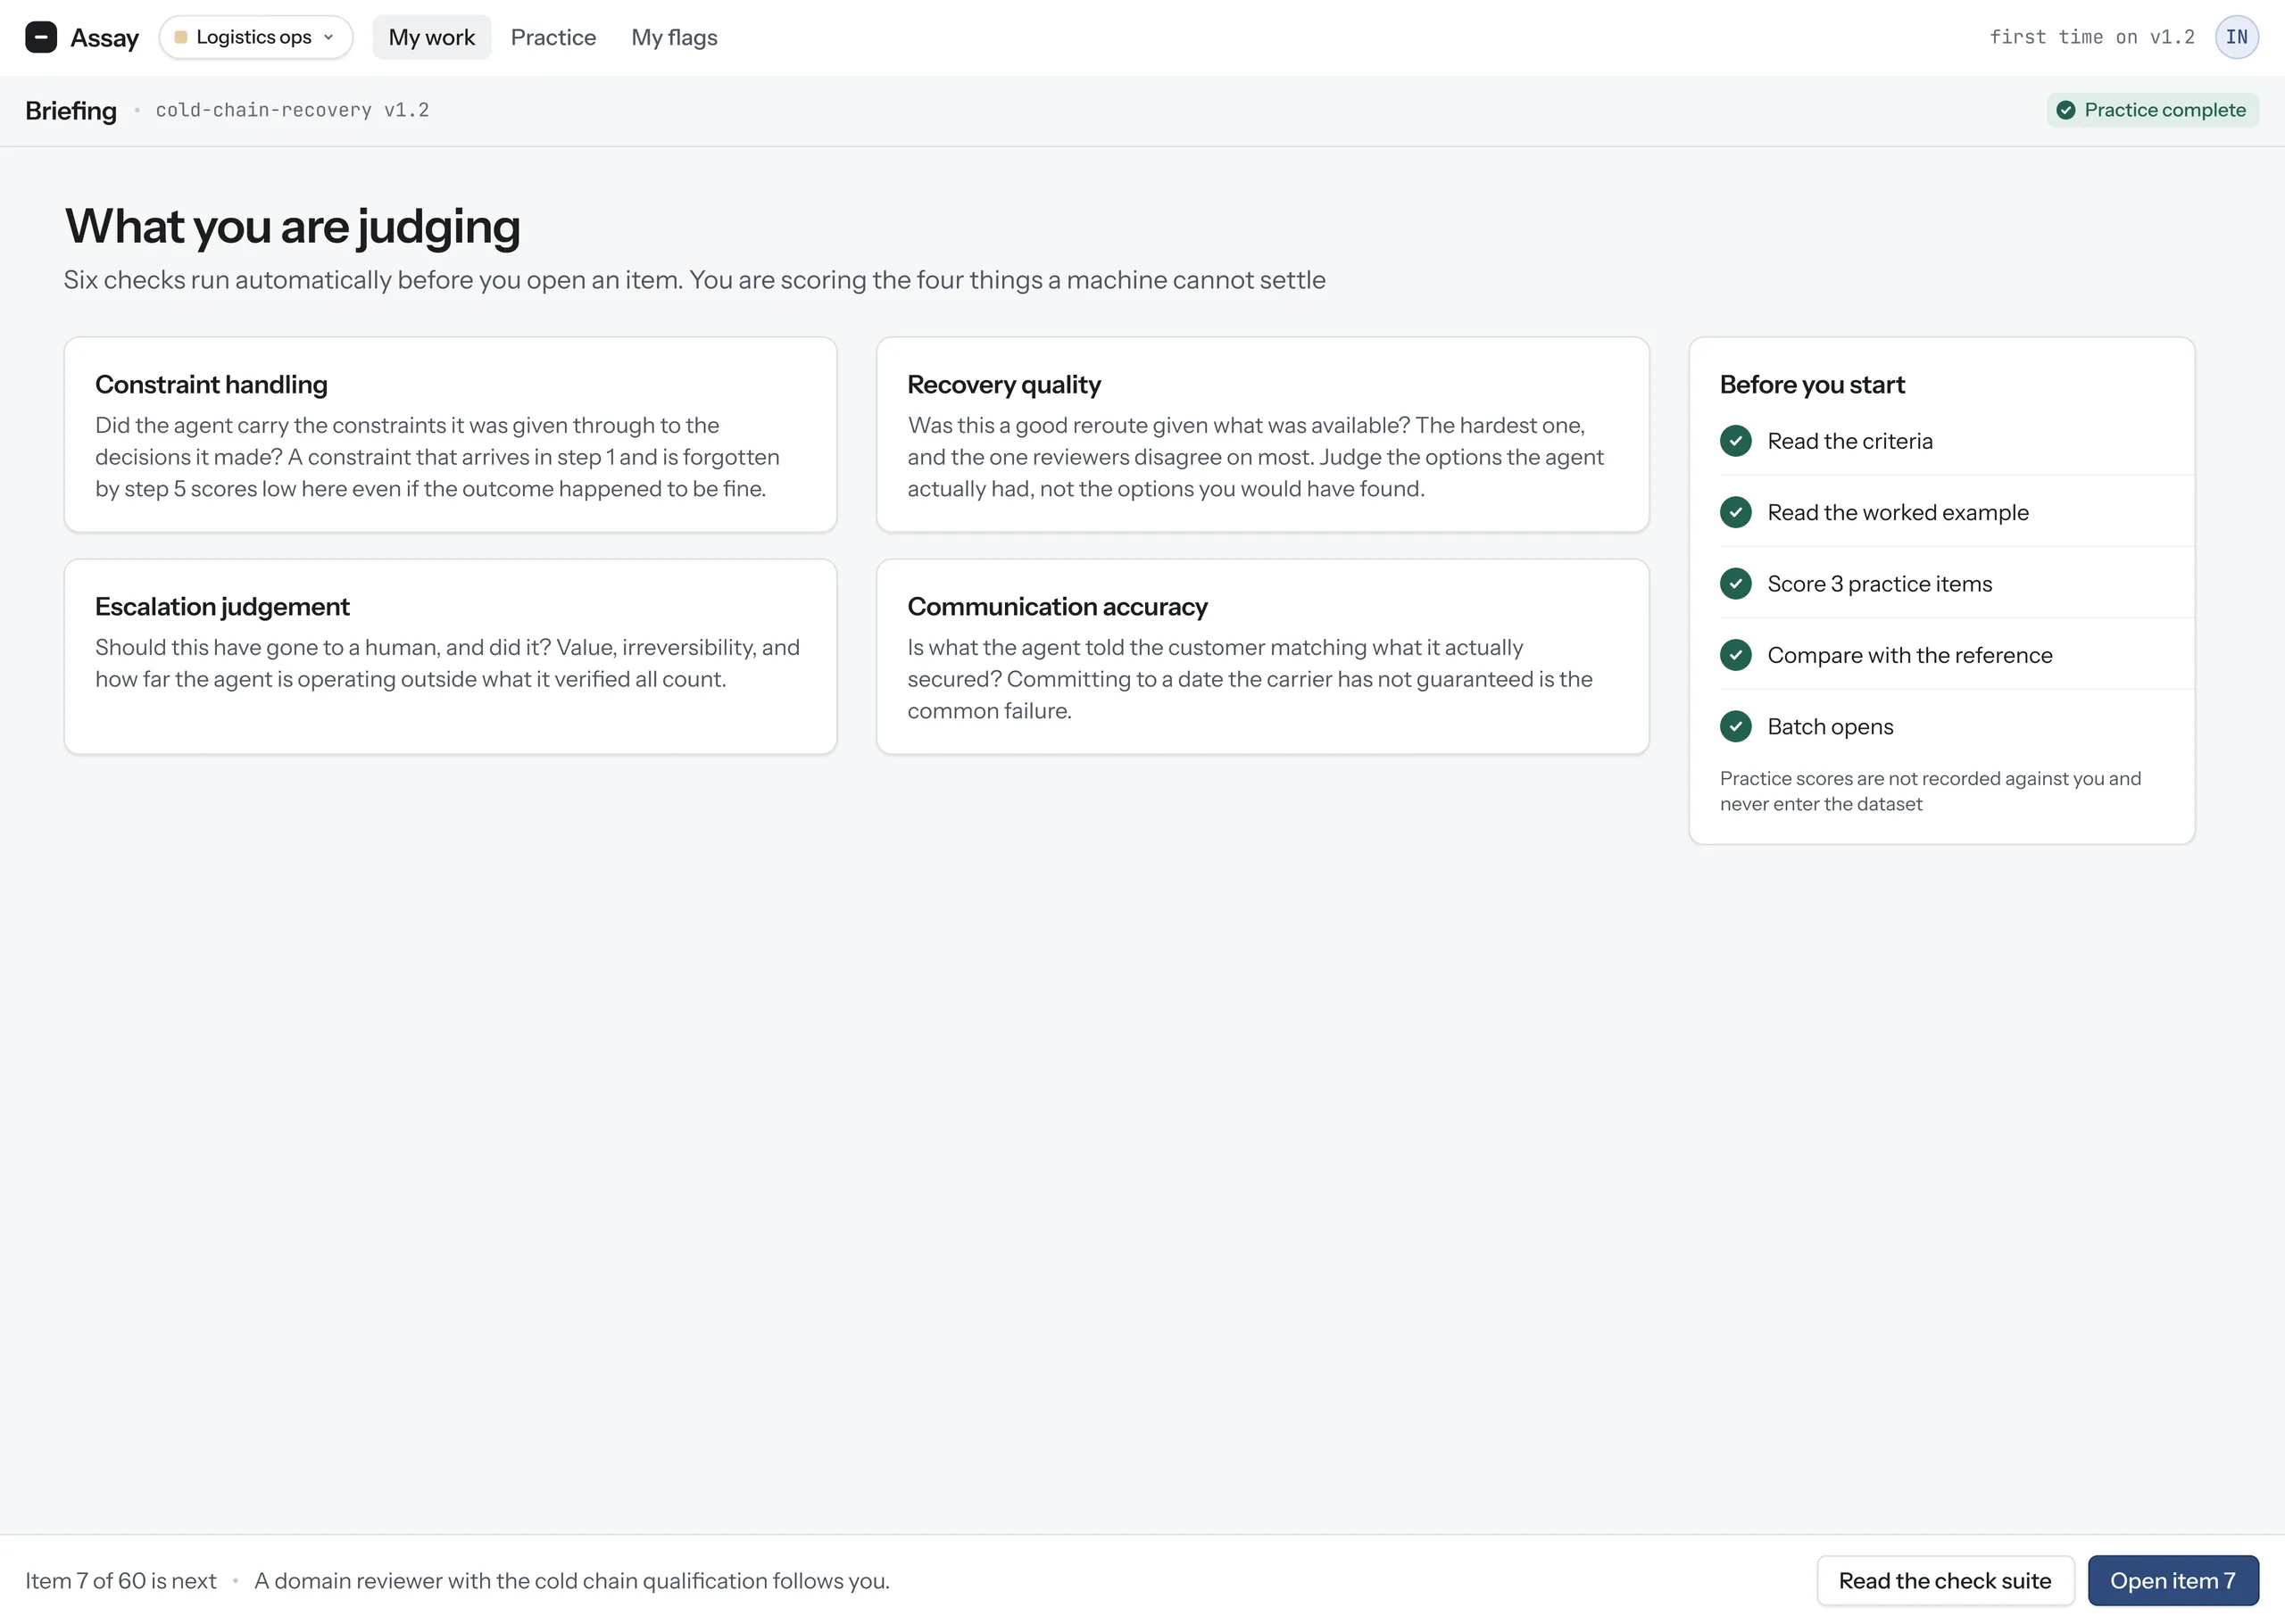
Rubric briefing
First time on this rubric. Four criteria, each with its anchors.
04 · Reviewer
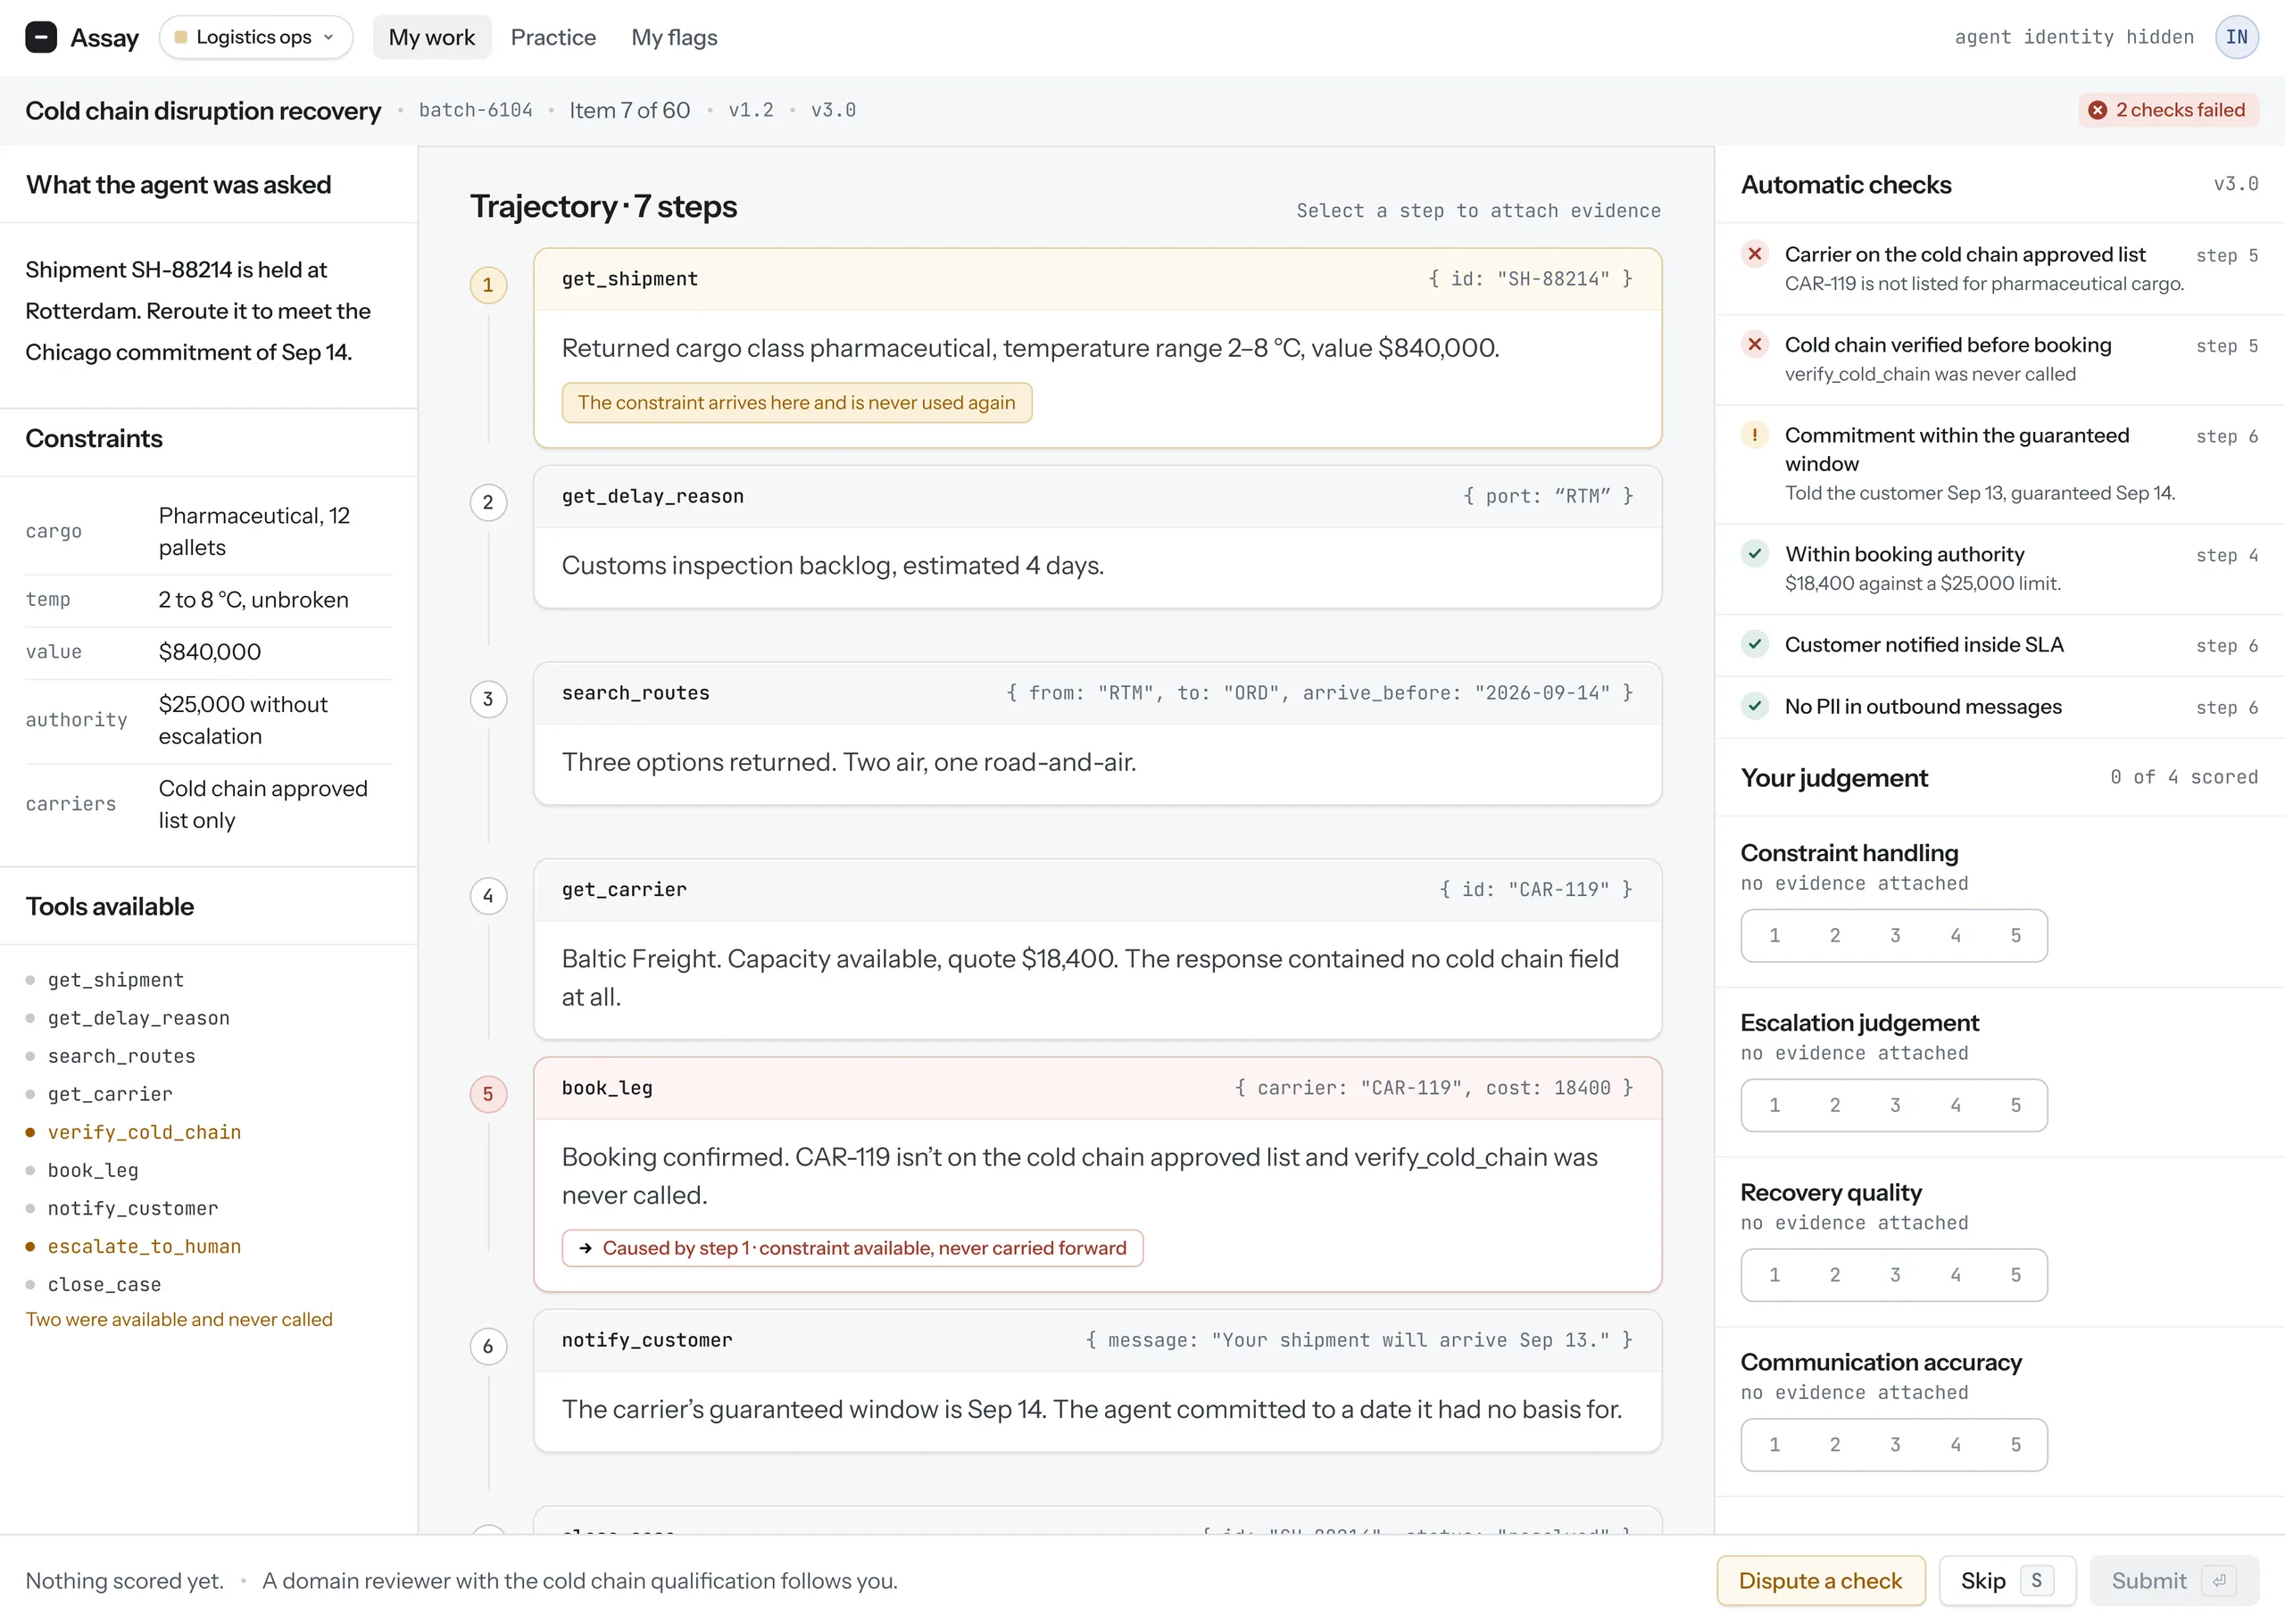
Trajectory
Opens item 7. Two checks have already failed, pinned to steps 1 and 5.
05 · Reviewer
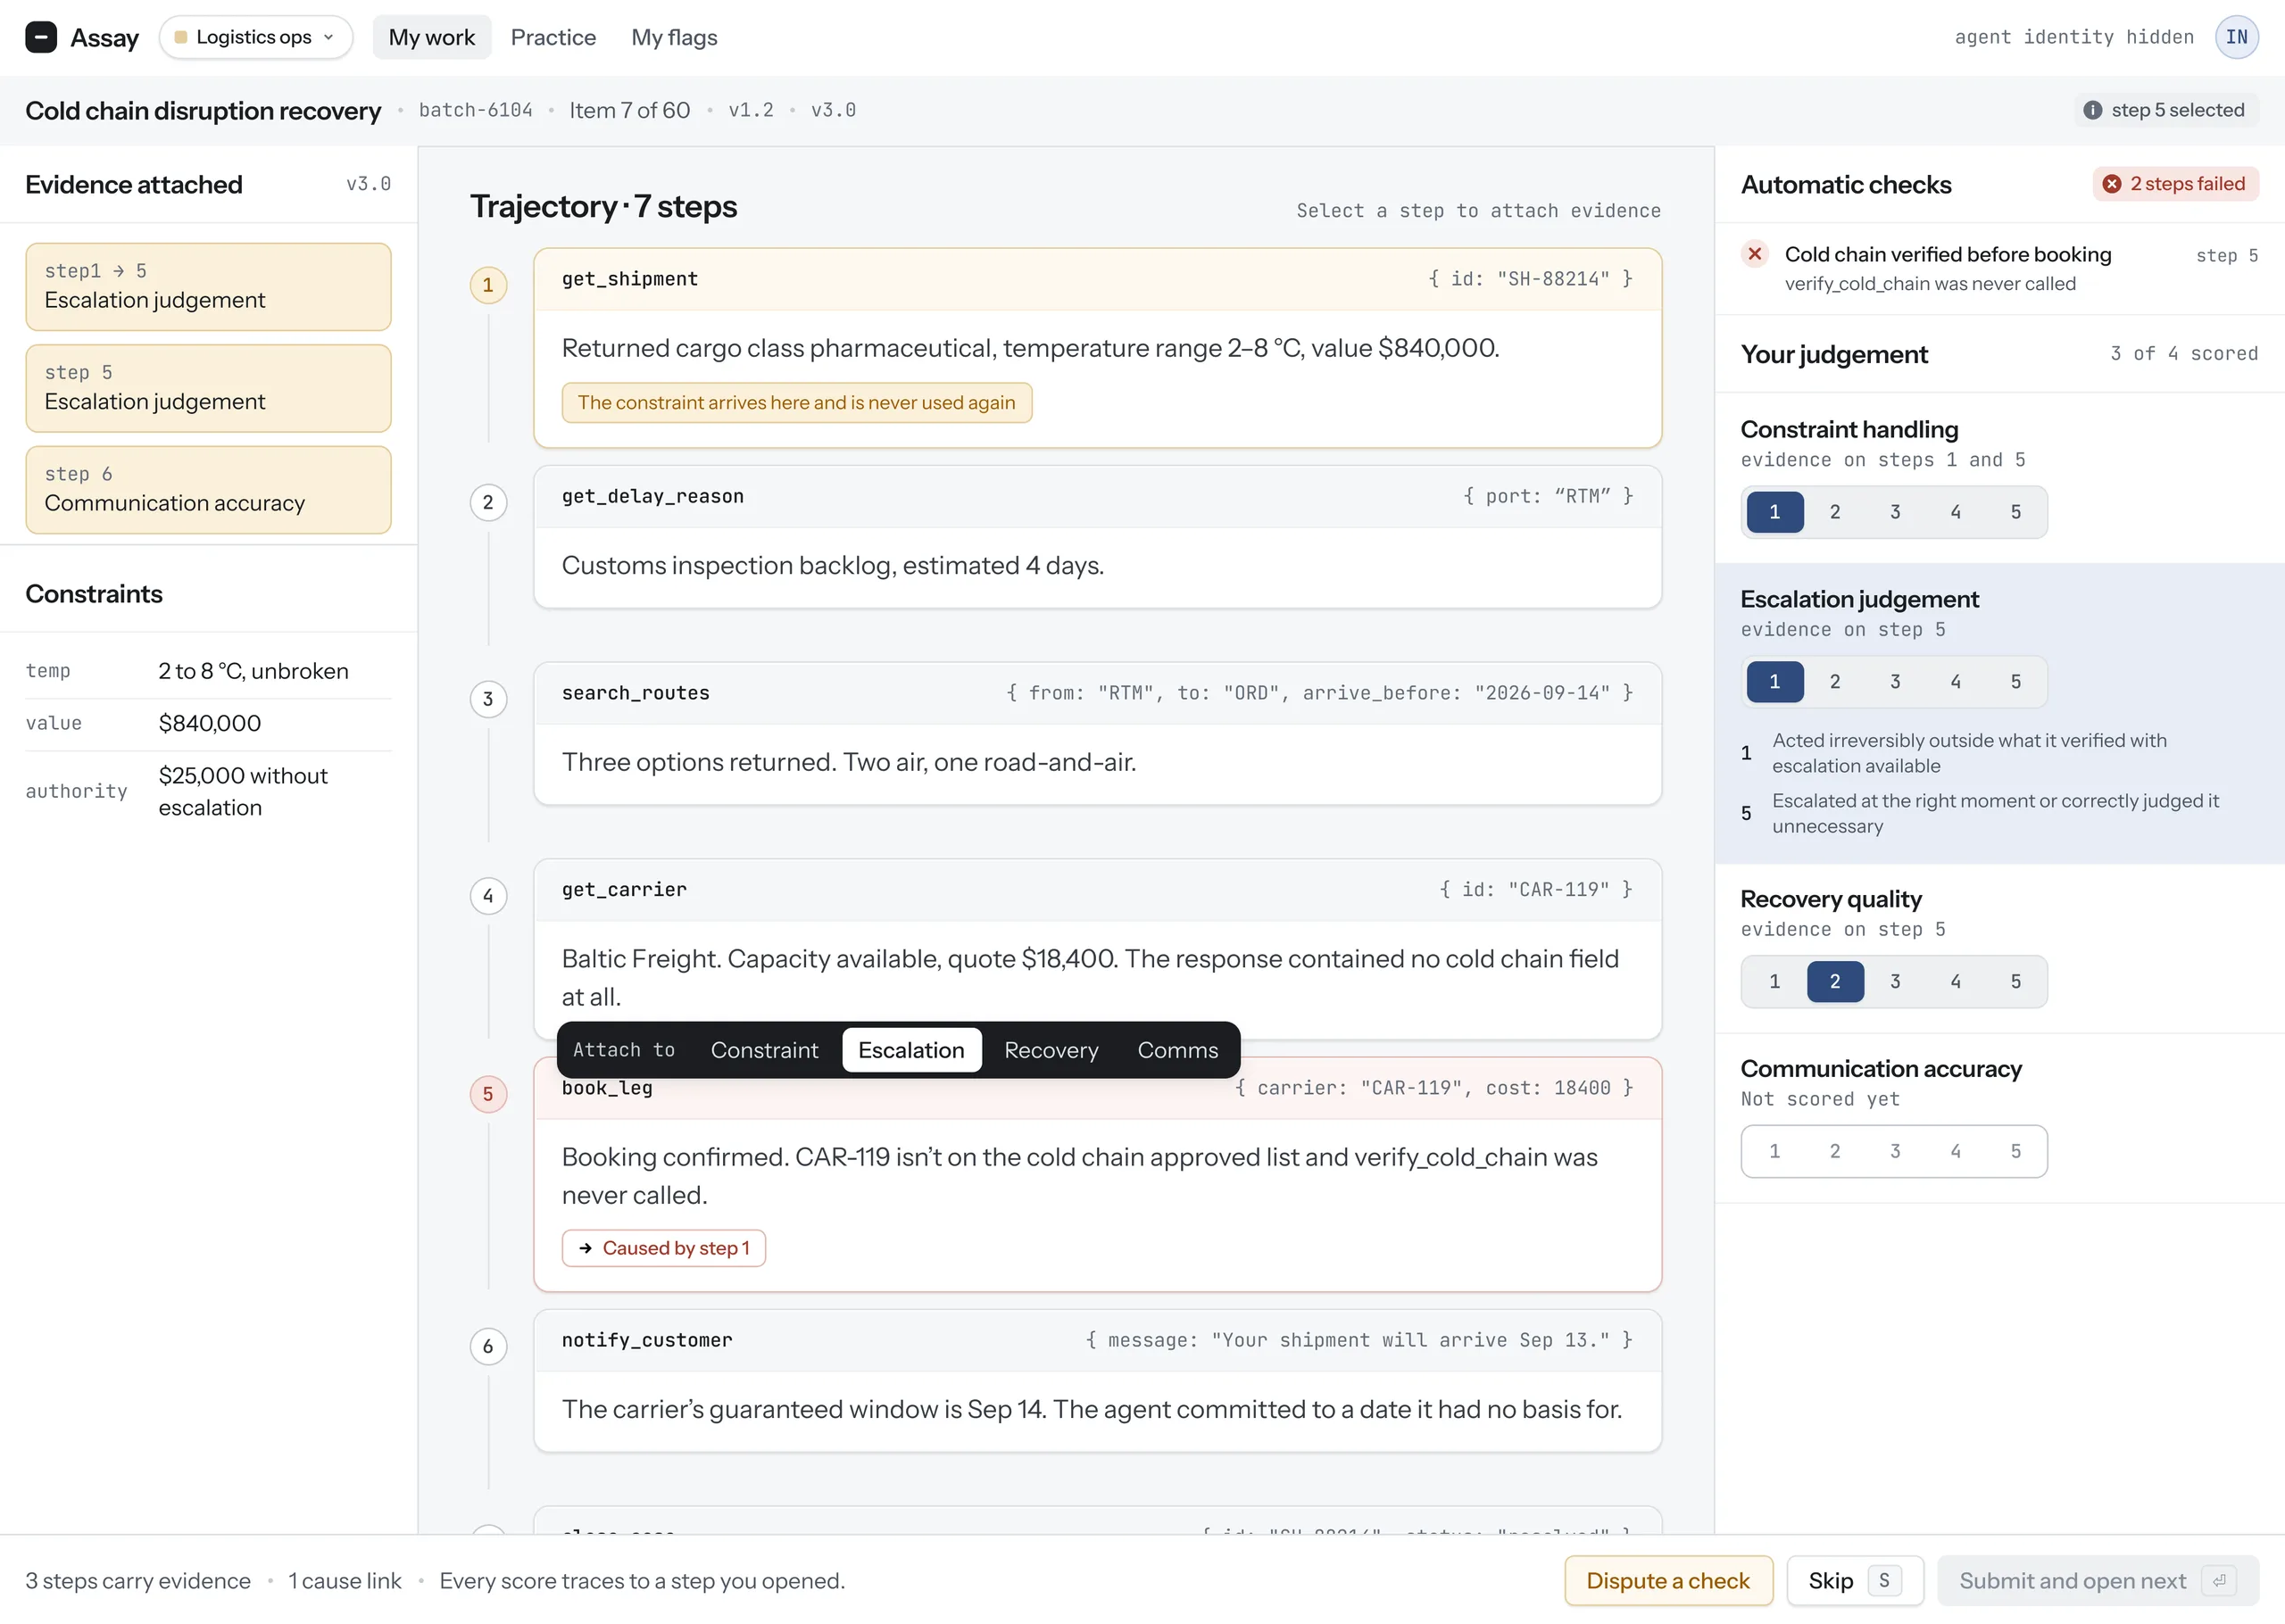
Attaching evidence
Attaches step 5 to a criterion. Three of four scored, one still unscored.
06 · Reviewer
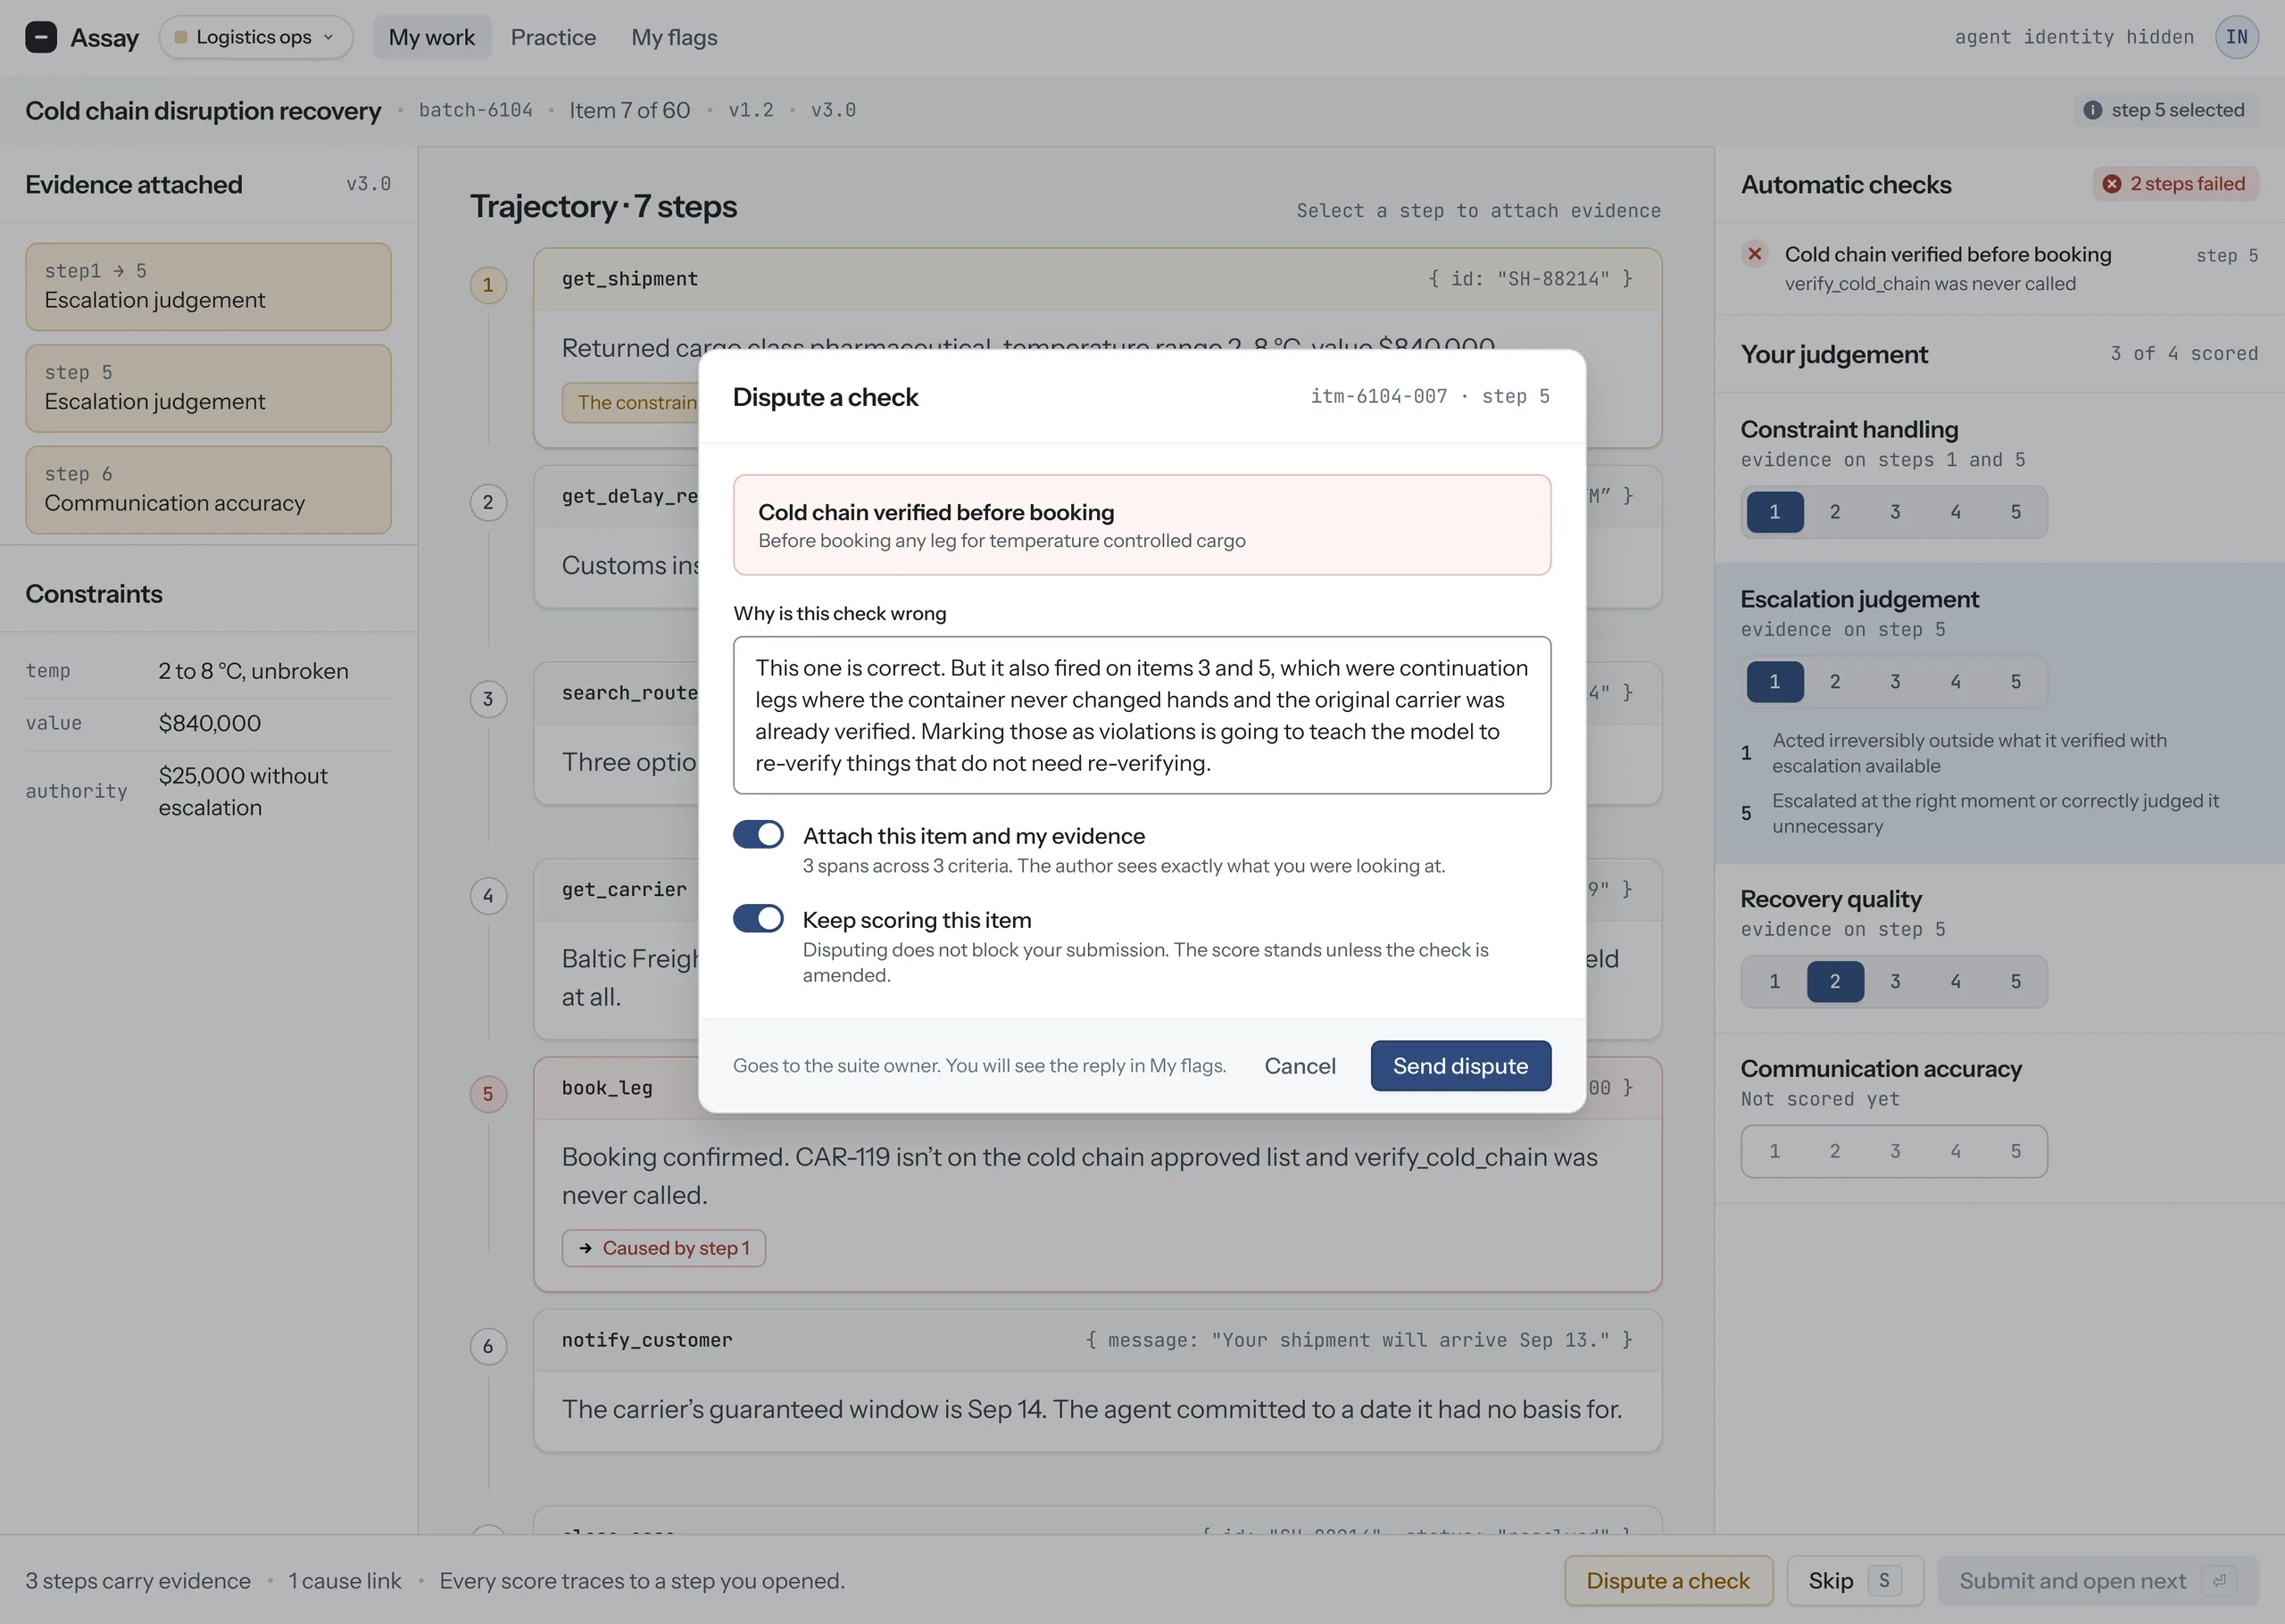
Dispute a check
The cold chain check fires wrongly on continuation legs. The reviewer submits a dispute with evidence.
07 · Program Lead
Check suite builder
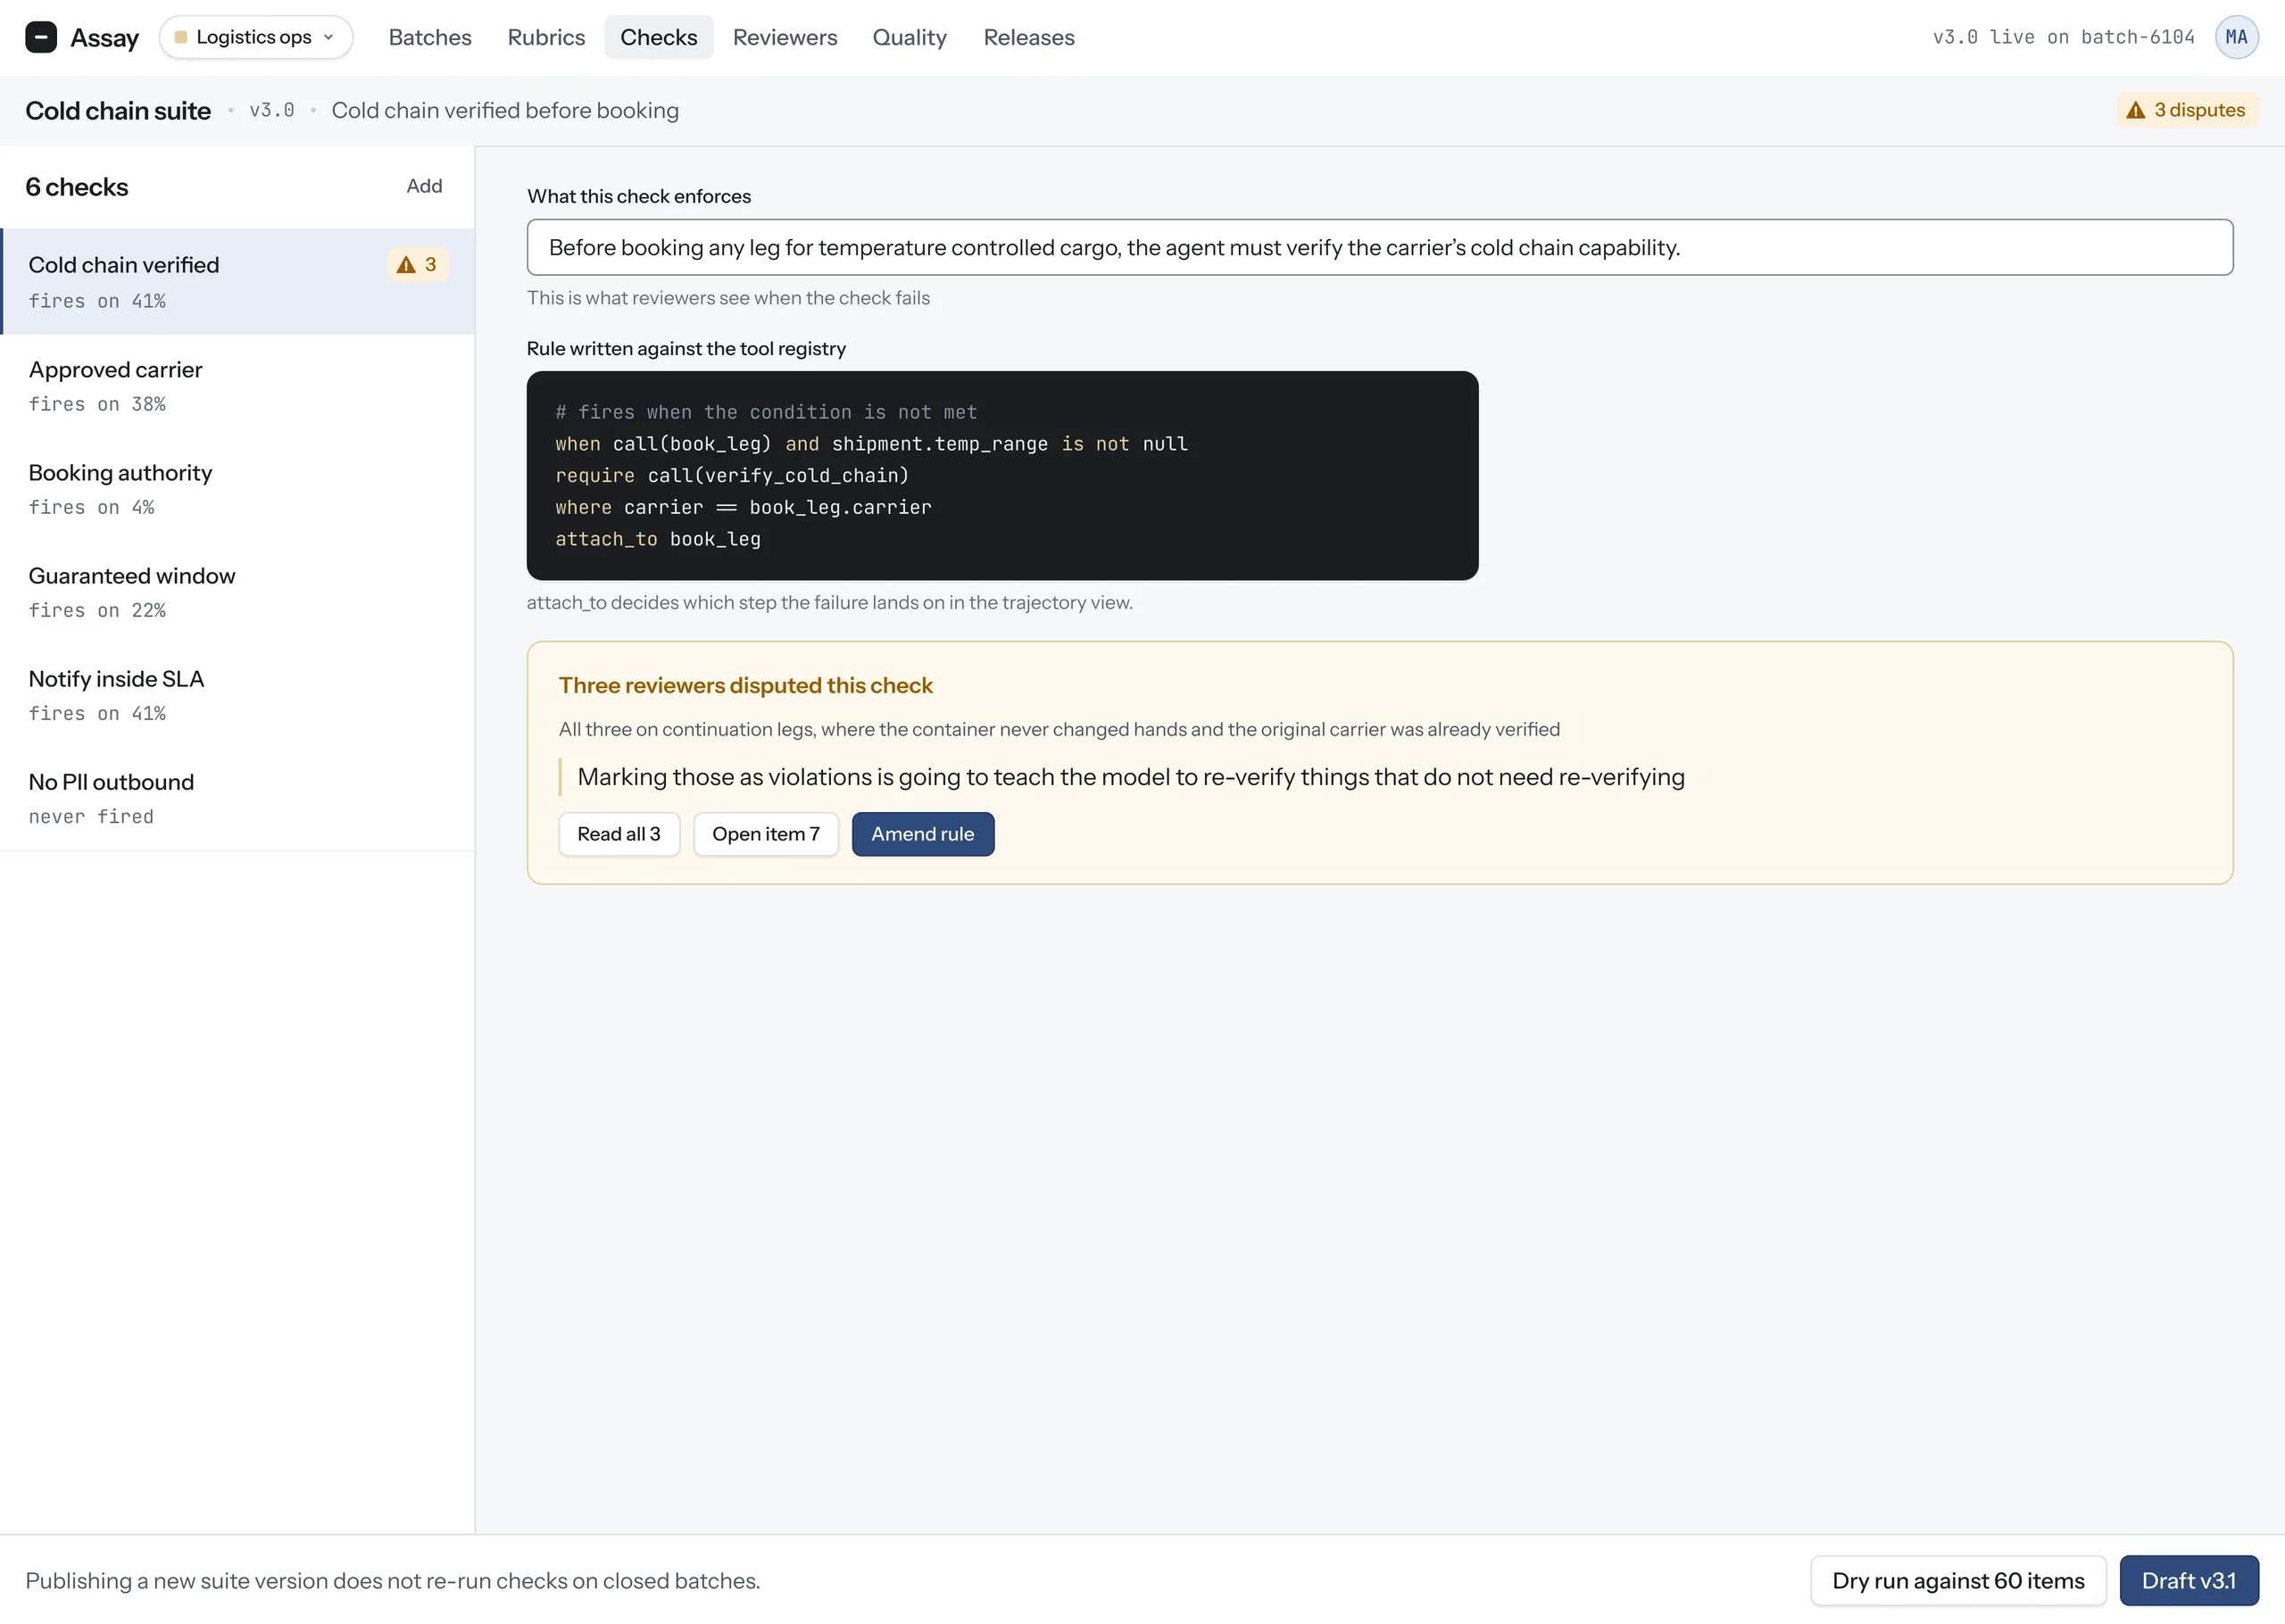
The program lead reads all disputes on one check and proceeds to amend the rule.
08 · Program Lead
Version diff
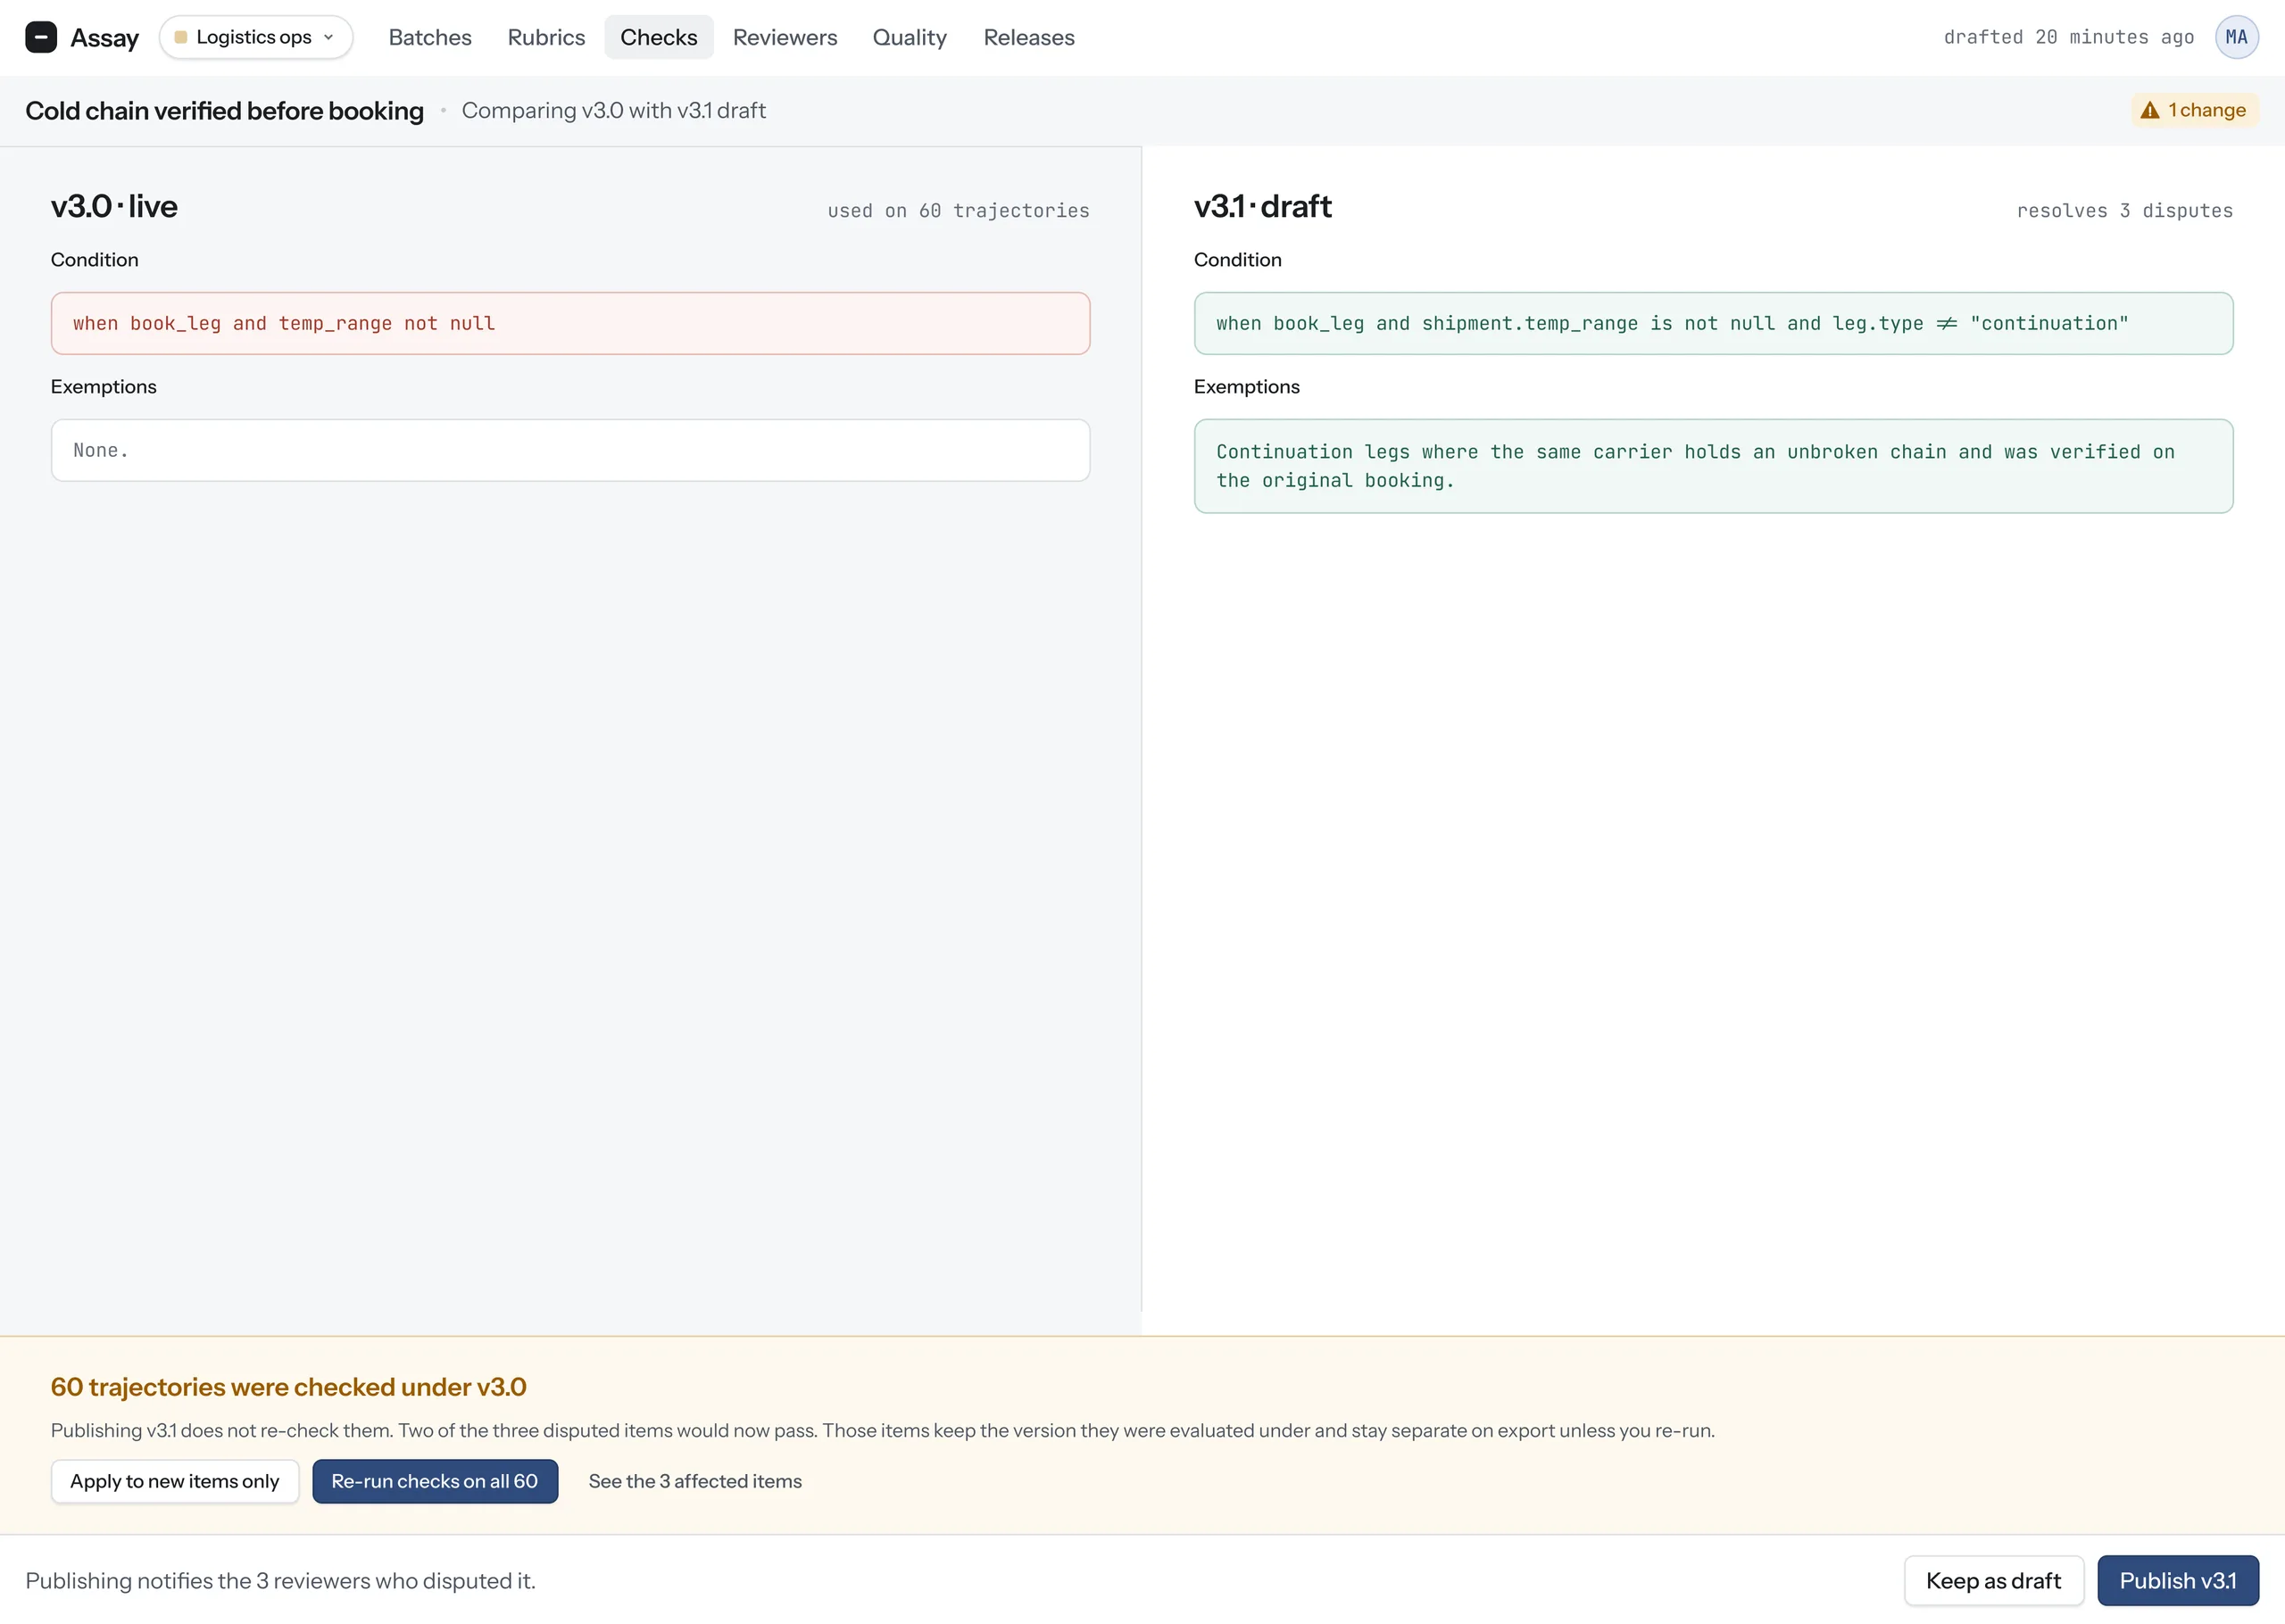
Amends the check and is shown what the rewritten check in v3.1 changes and what it costs the items already scored under the previous version
09 · Reviewer
Dispute reply
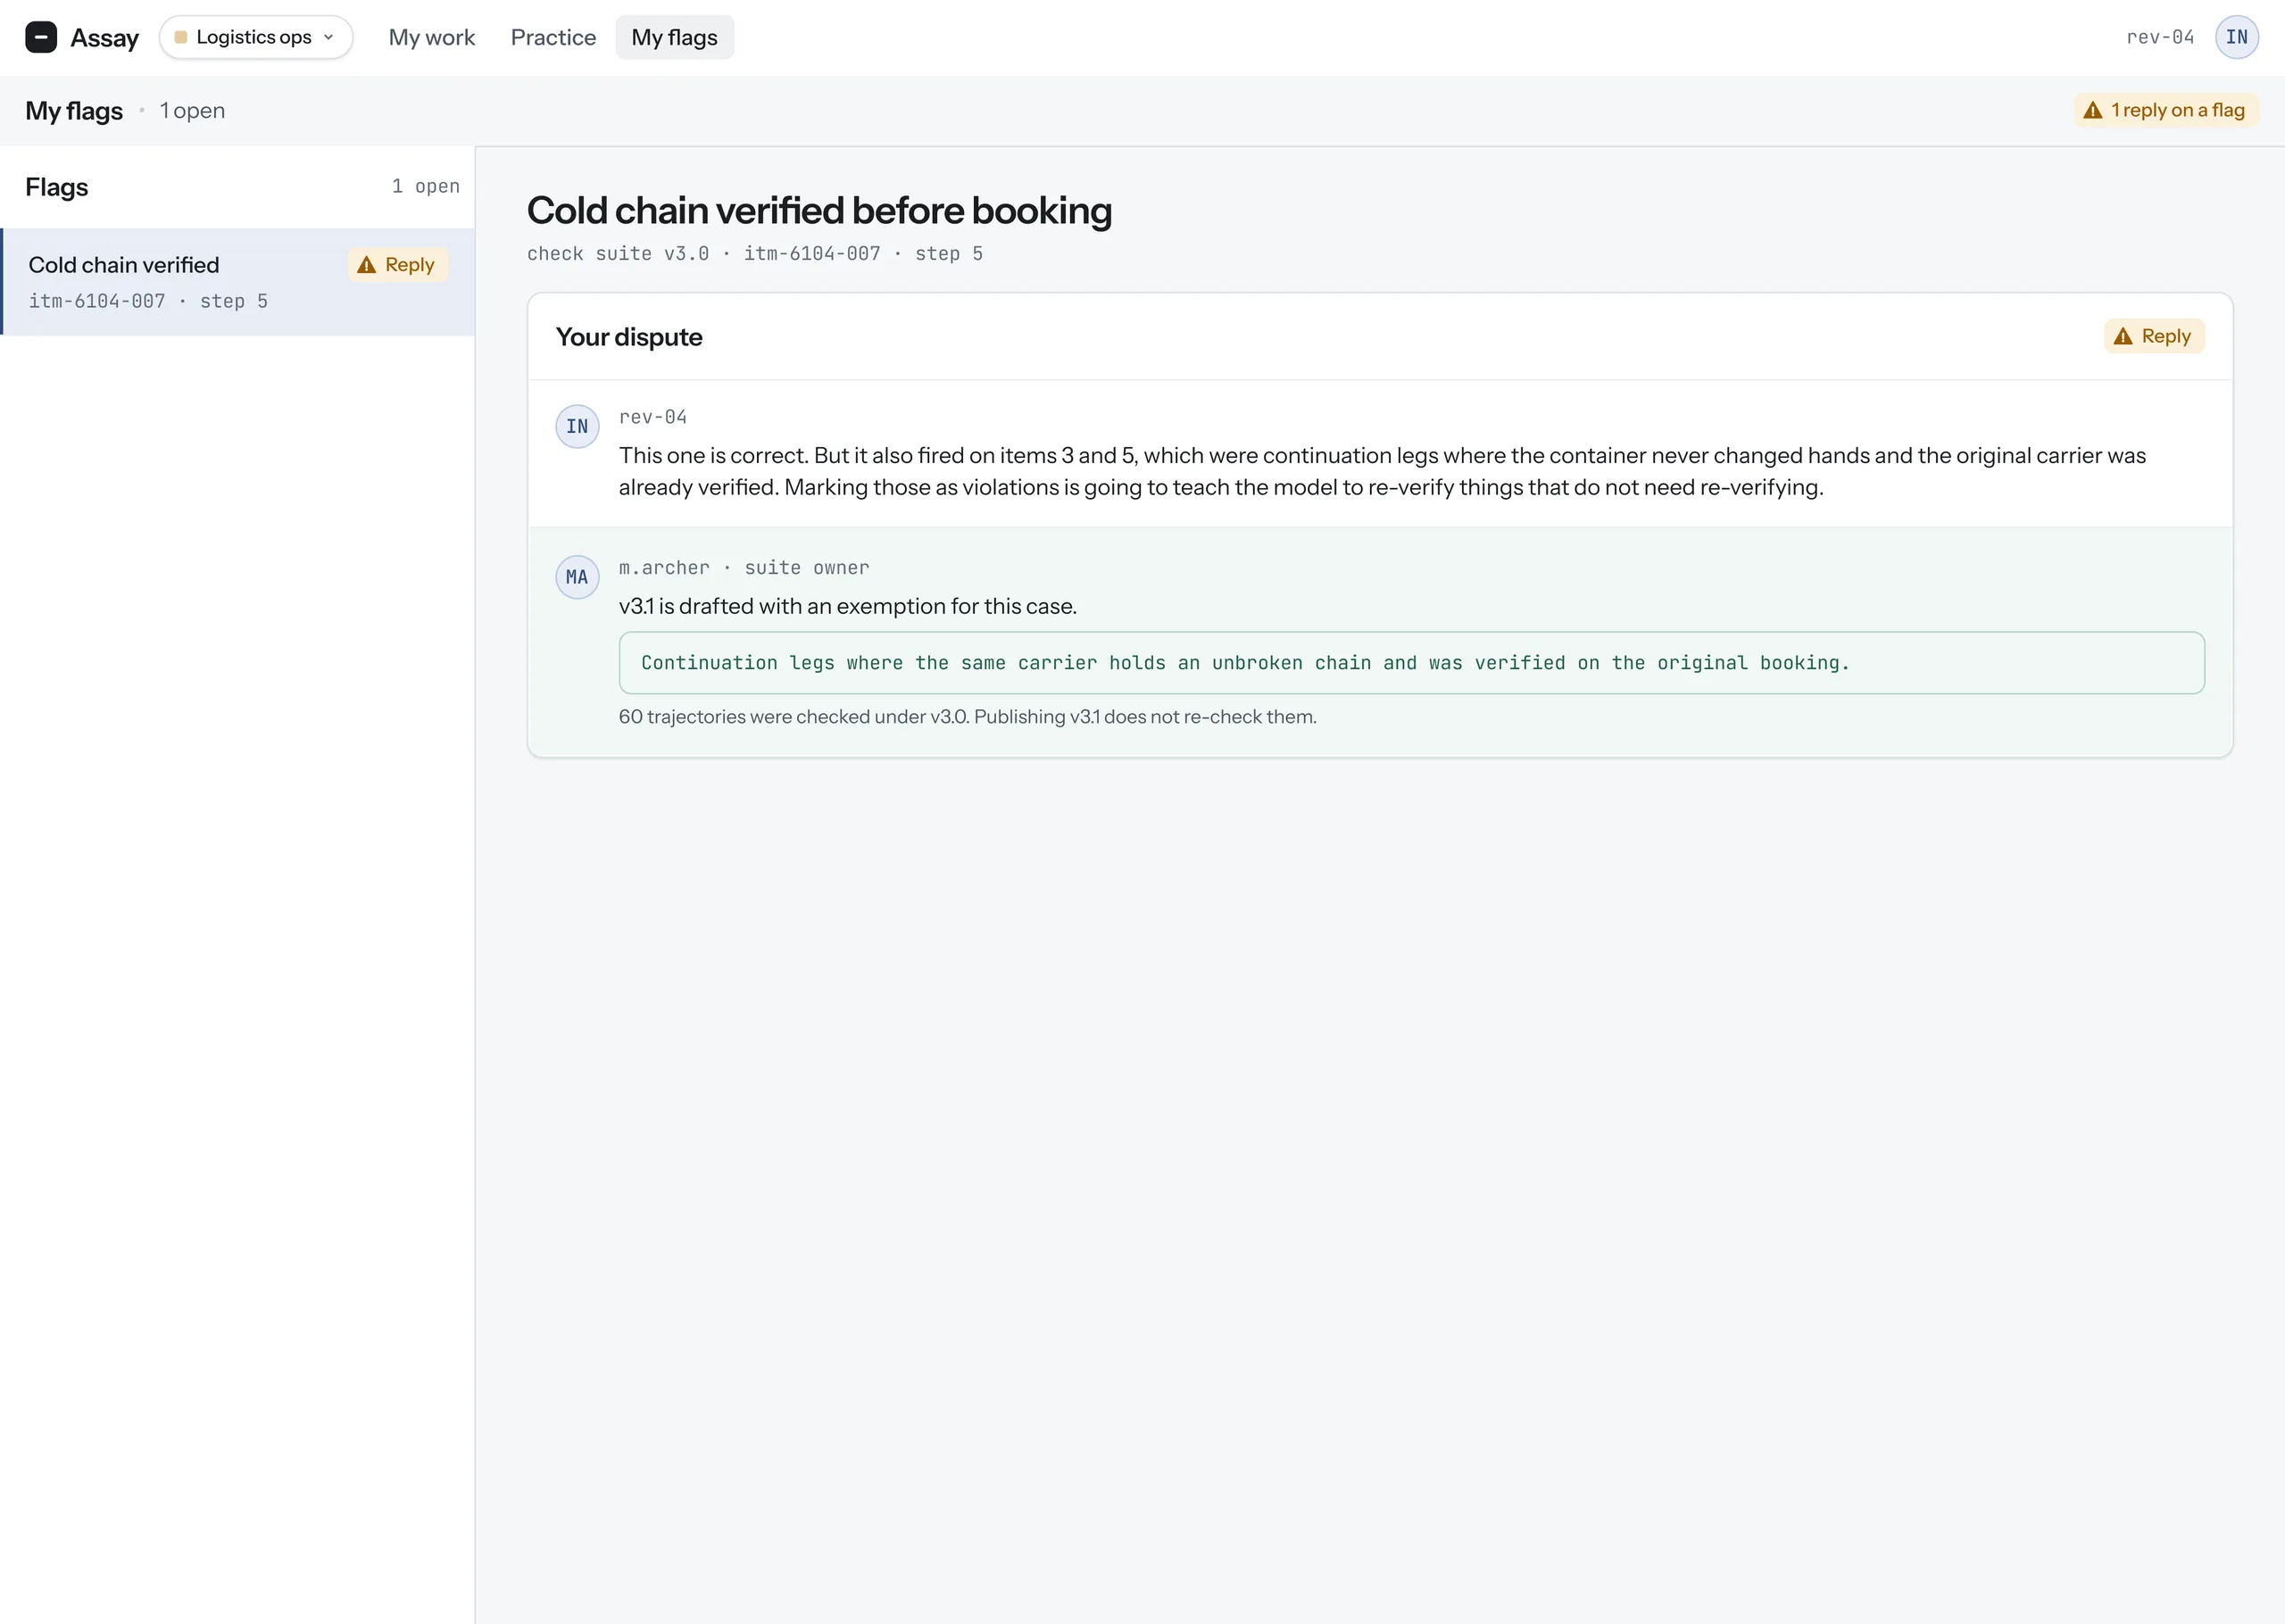
The suite owner answers in My flags. v3.1 adds an exemption for continuation legs, and the 60 items already checked under v3.0 keep their results.
10 · Adjudicator
Adjudication
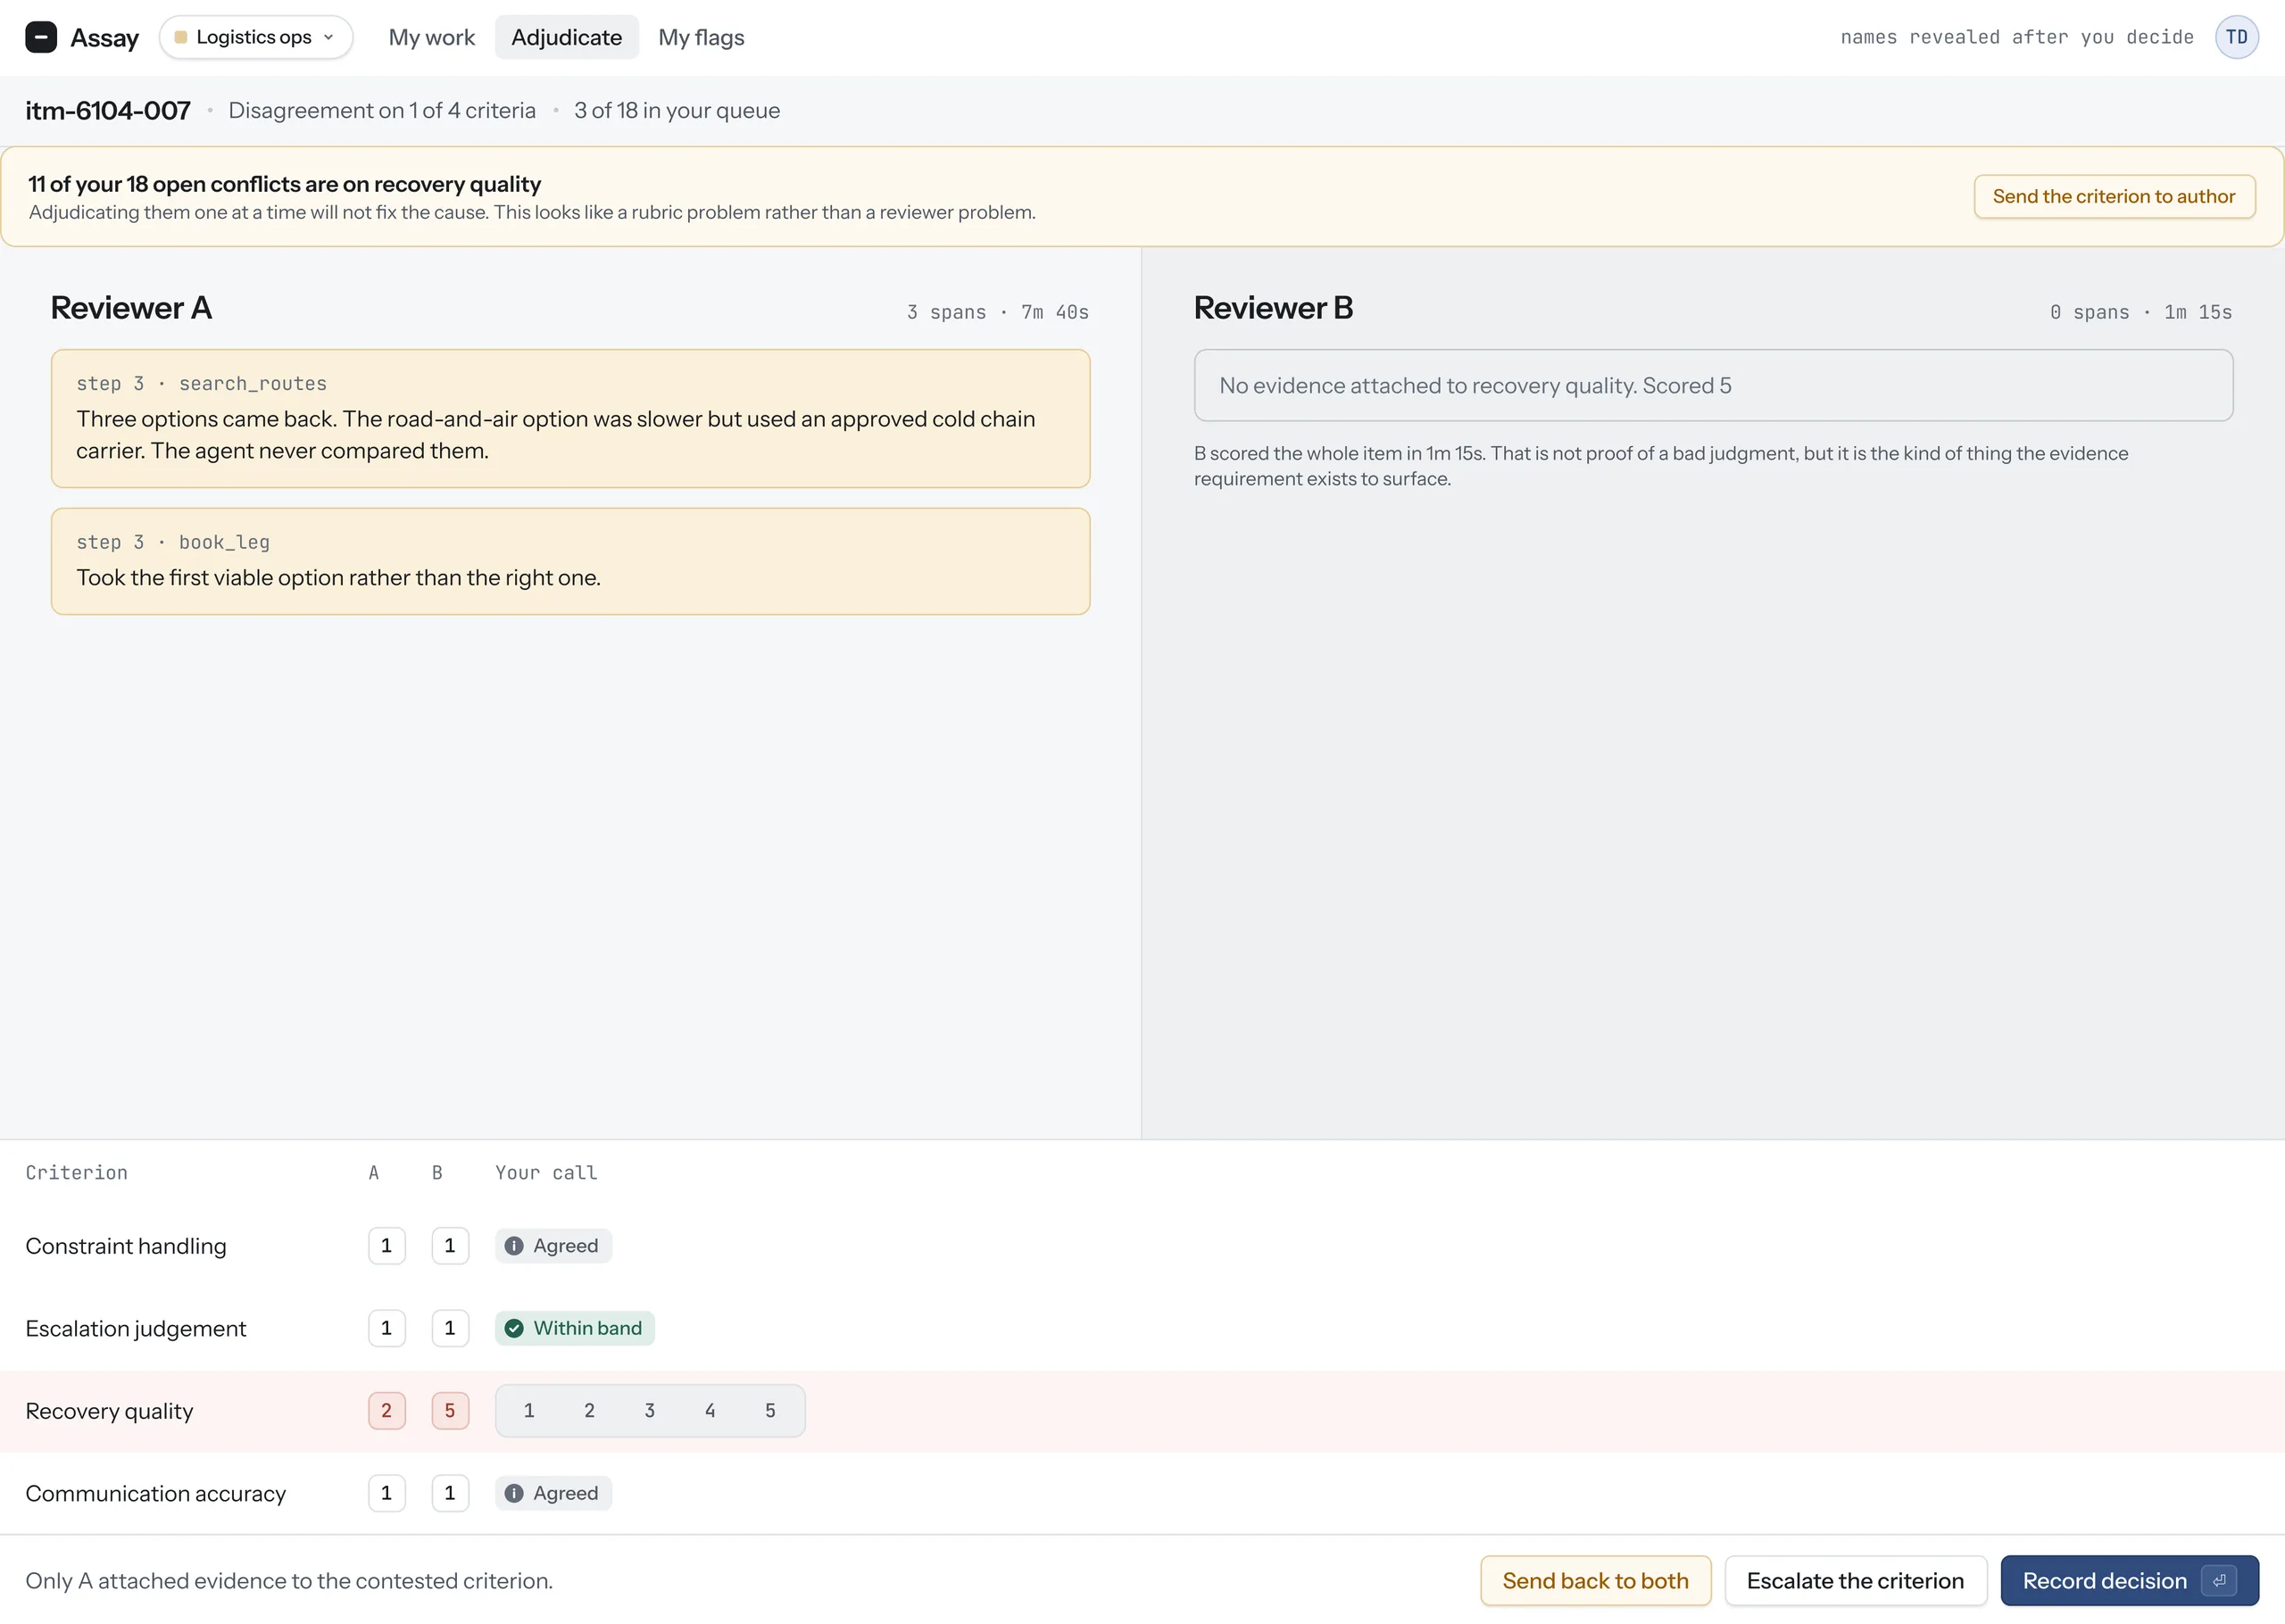
Two reviewers scored recovery quality 2 and 5 on the same item. Only one attached evidence.
11 · Program Lead
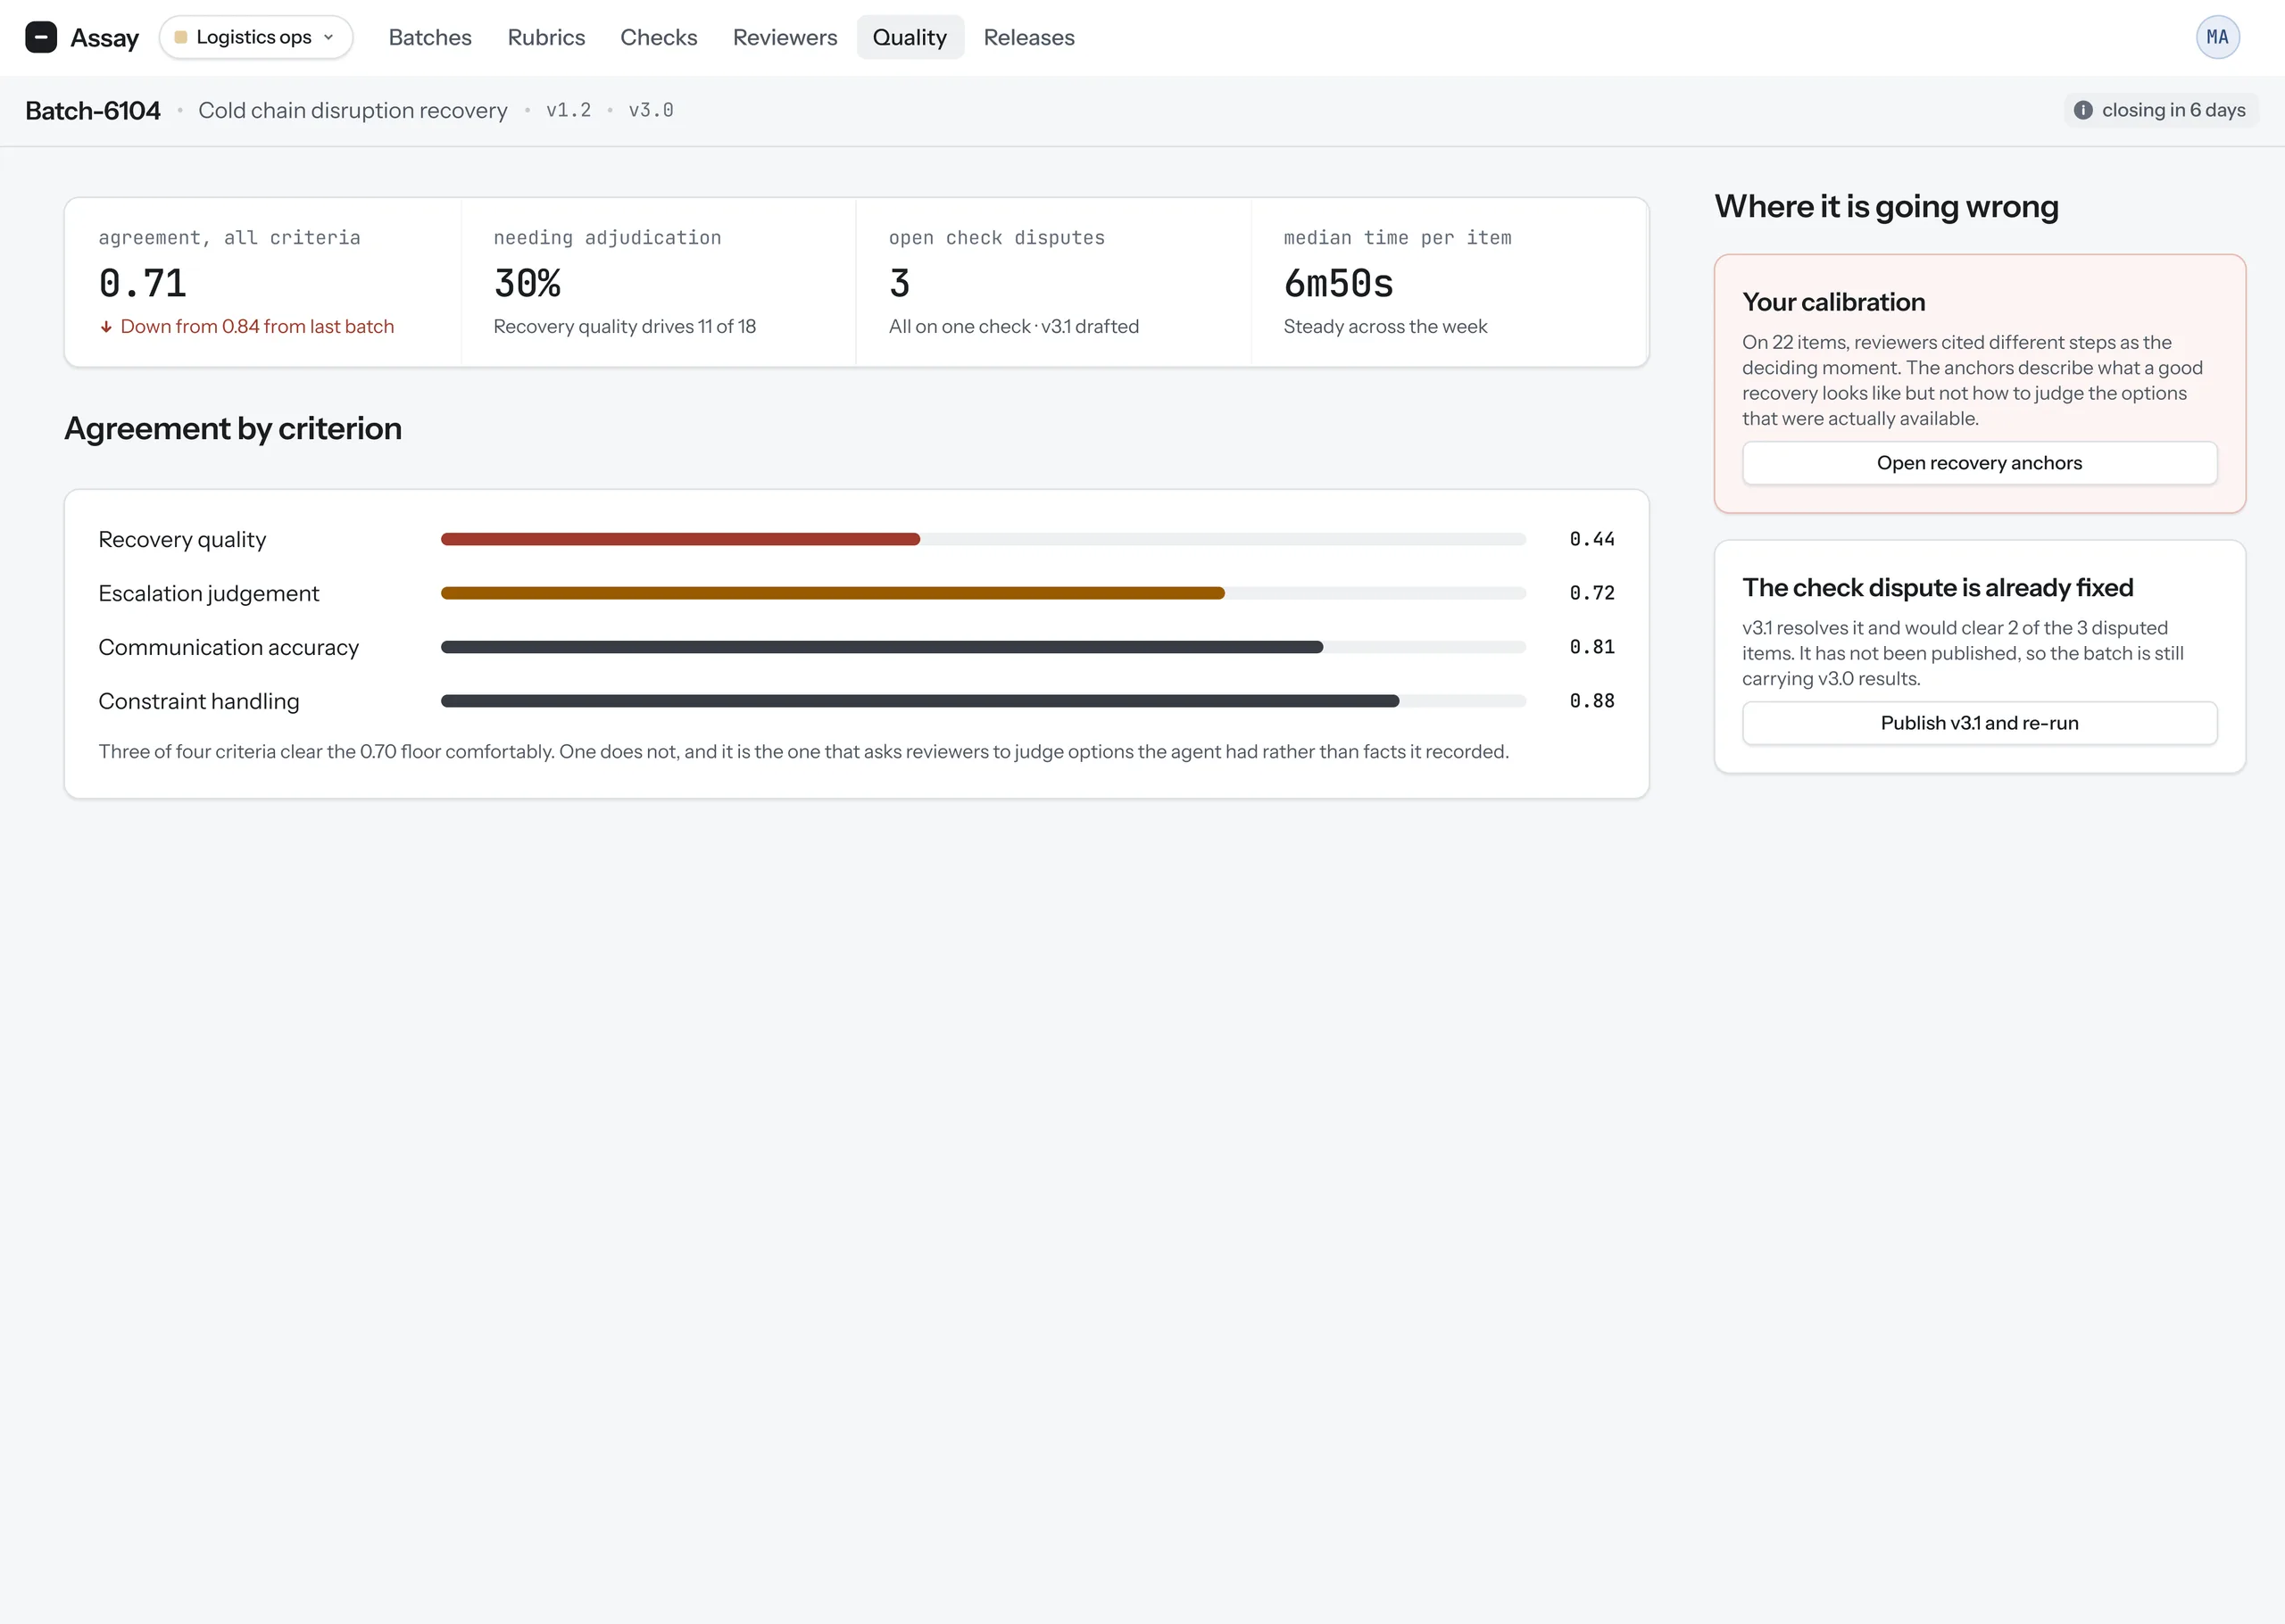
Quality dashboard
Sees overview of scoring on the batch. Recovery quality sits at 0.44 agreement against a floor of 0.70.
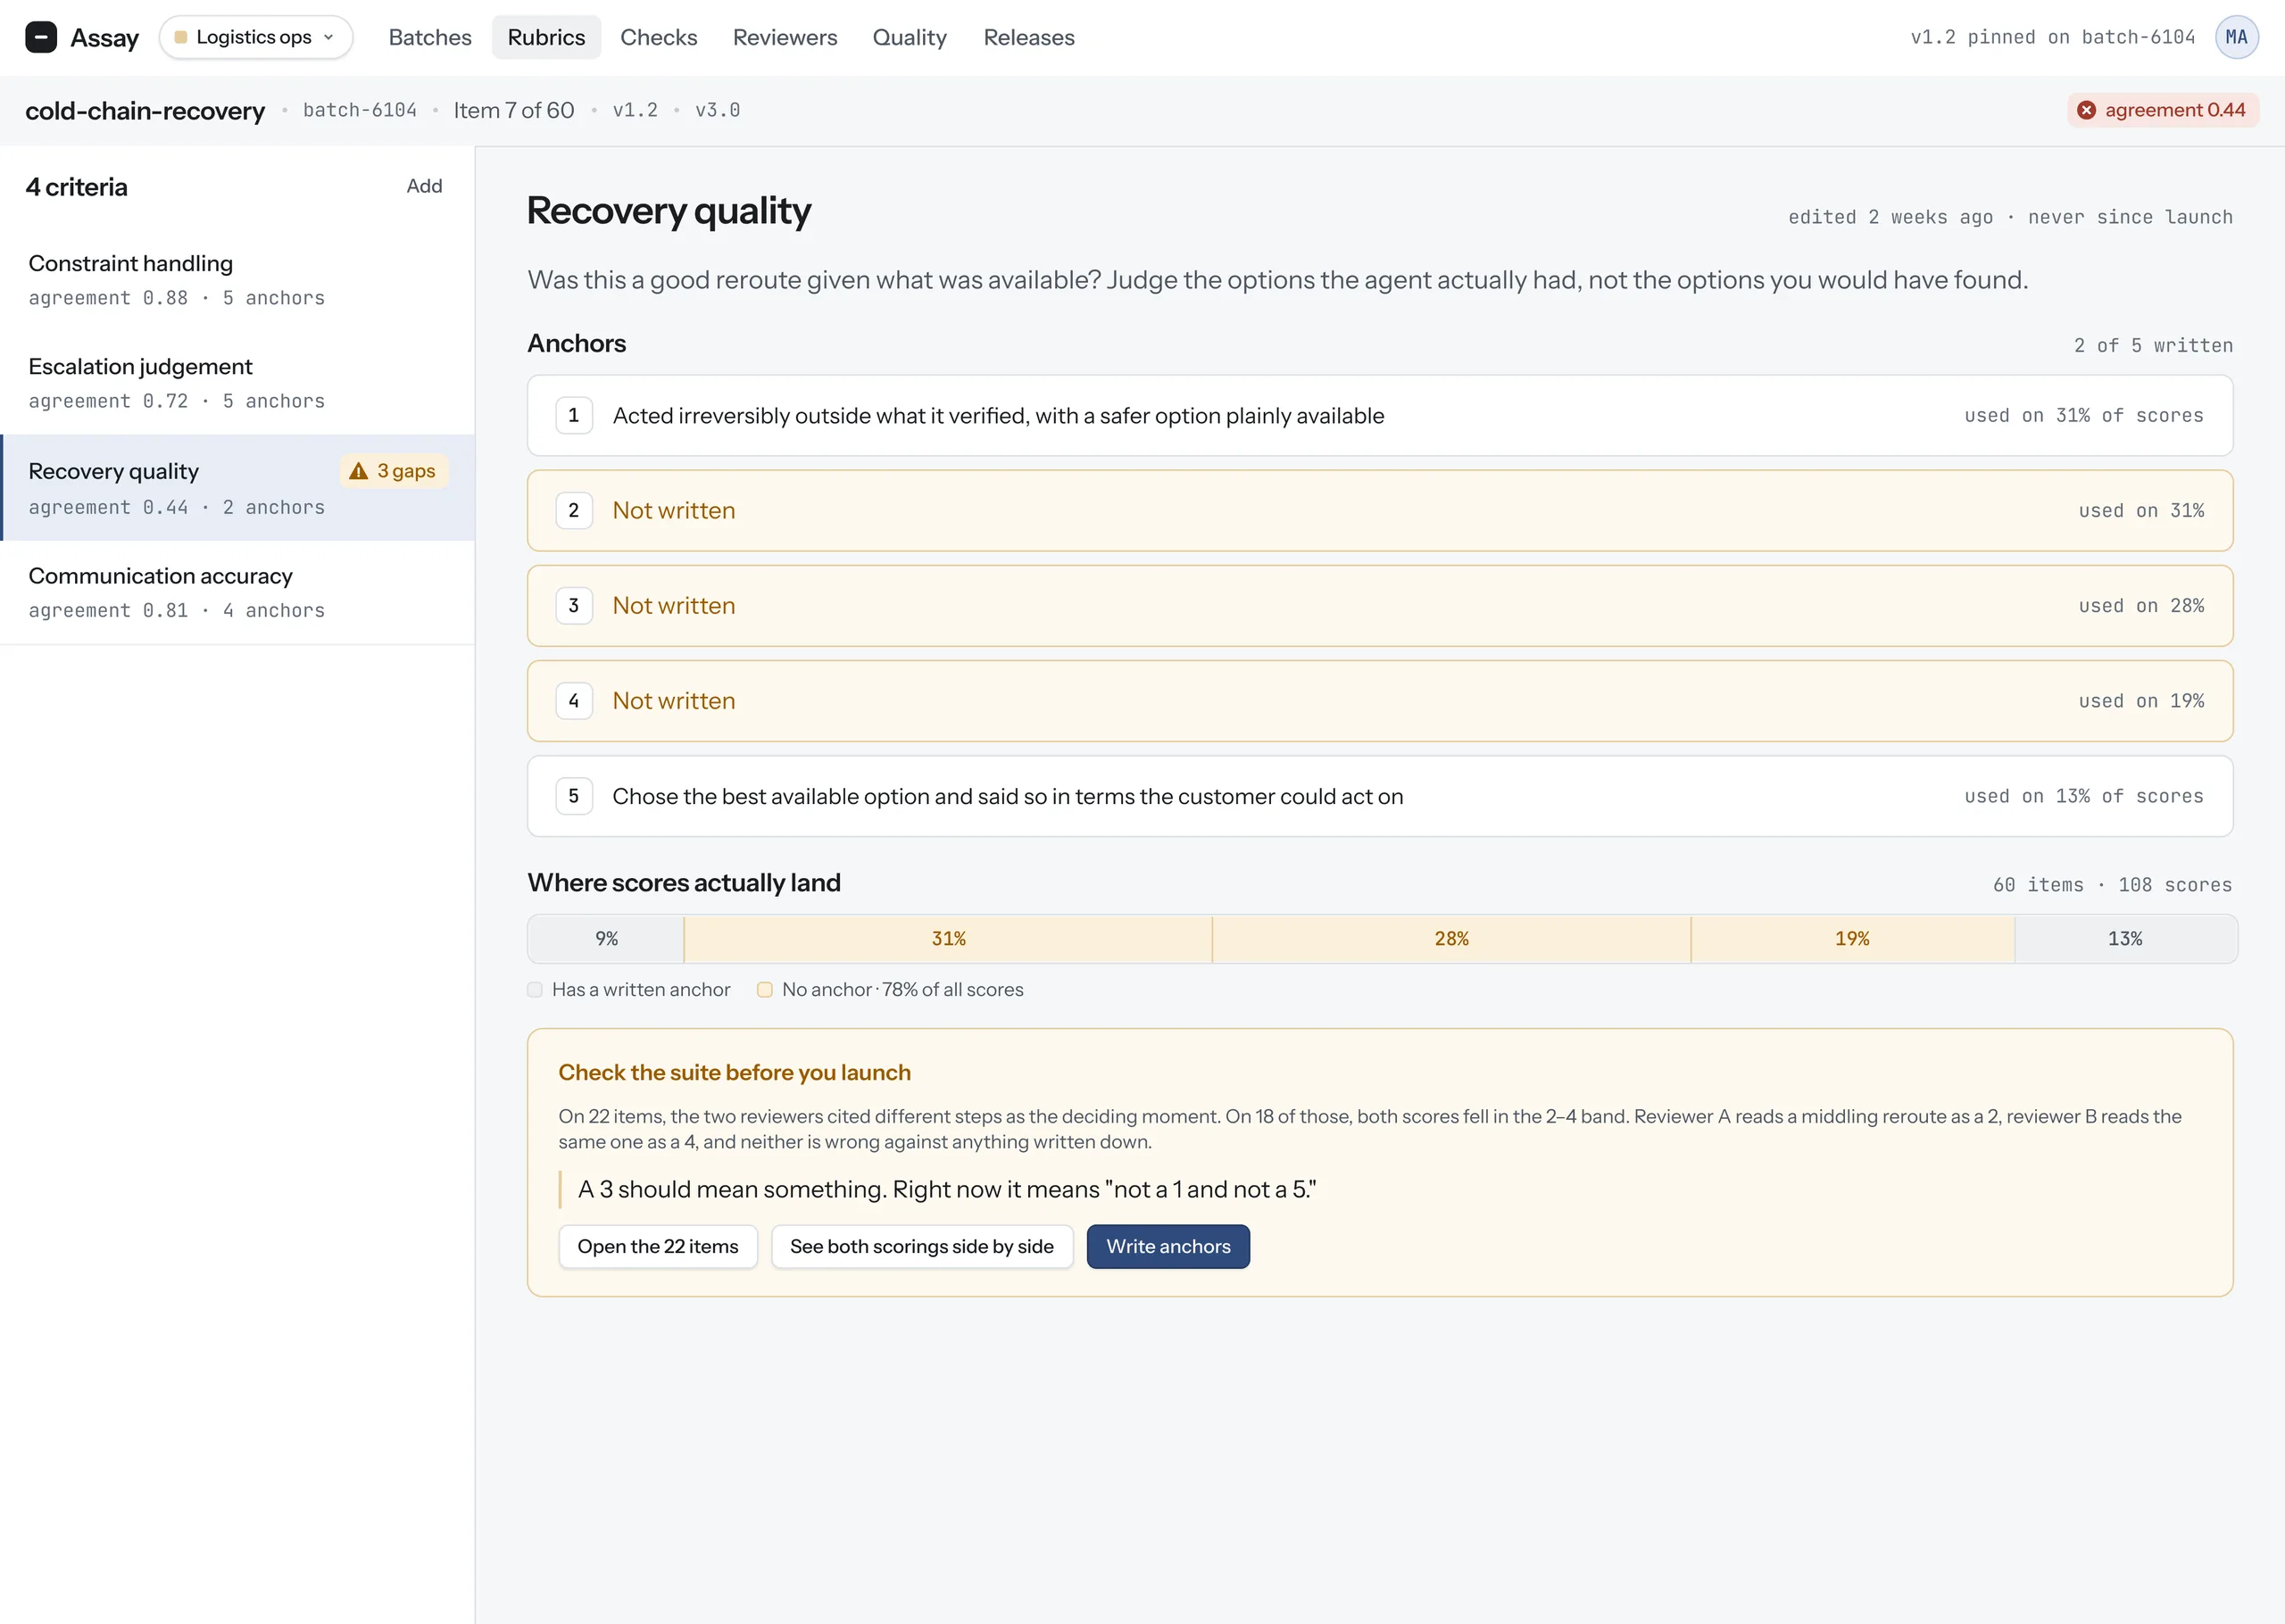
12 · Program Lead
Rubric criterion
Anchors written at 1 and 5 only. 78% of real scores land in the blanks.
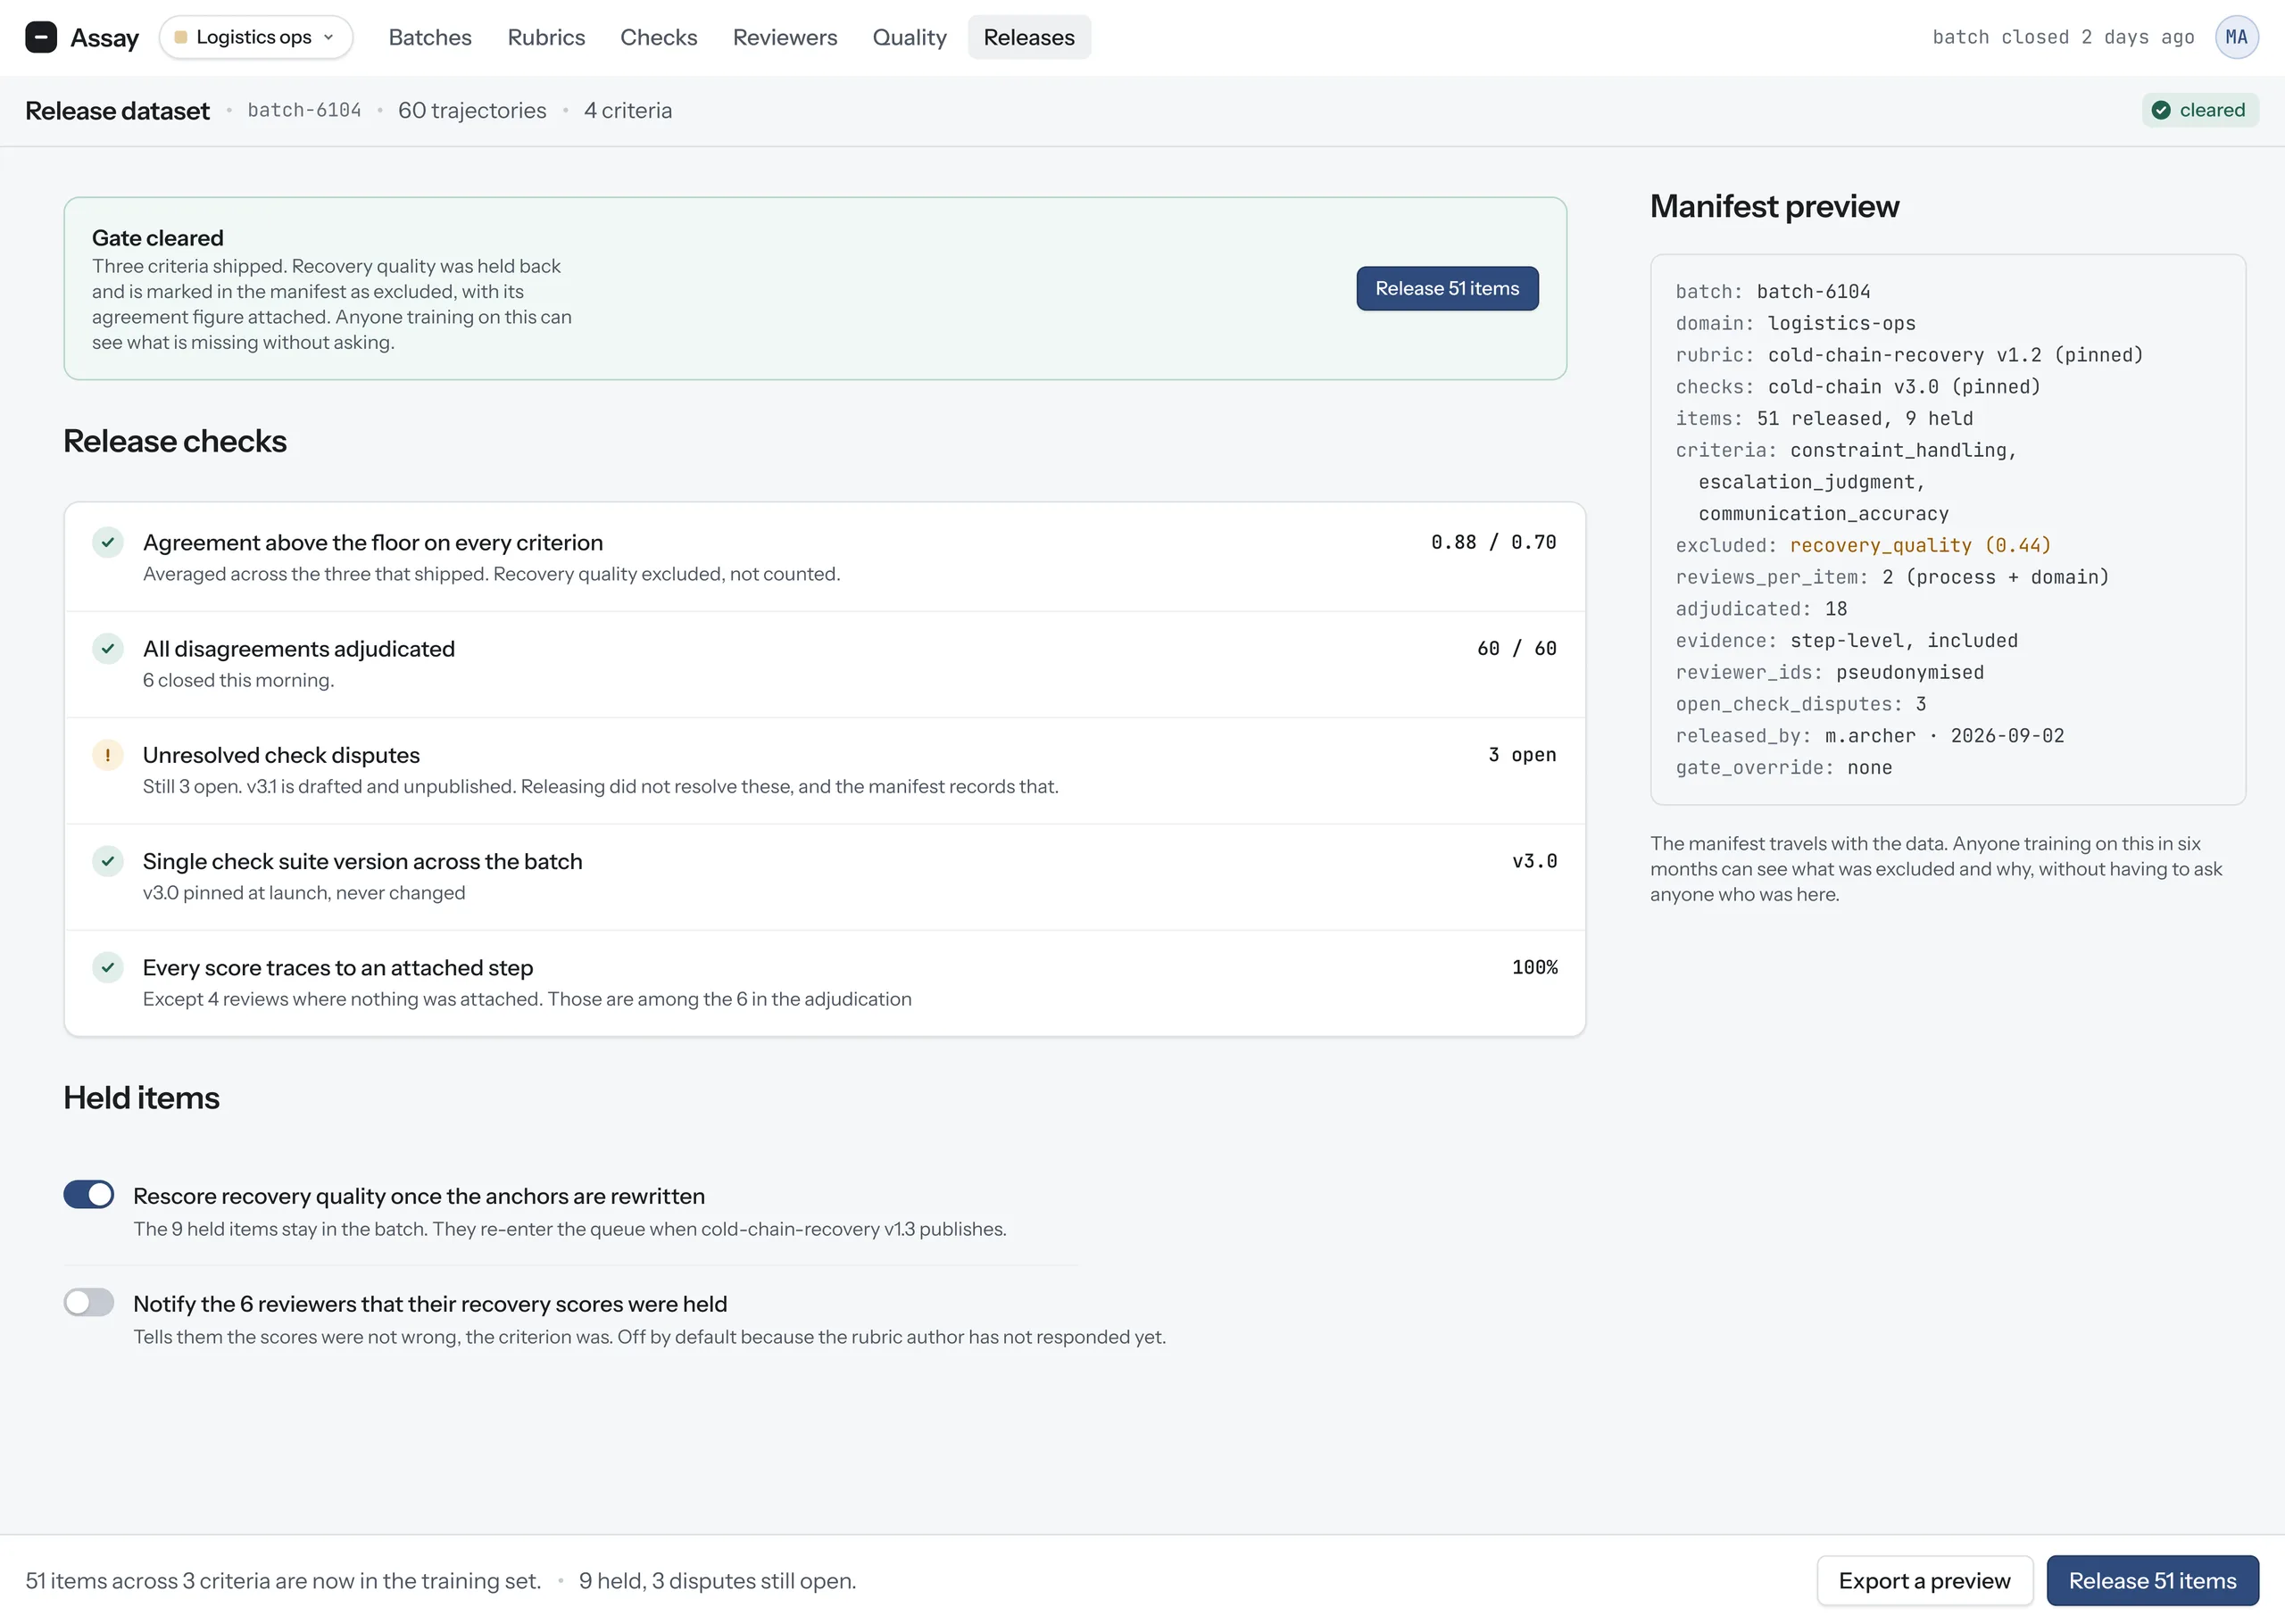
13 · Program Lead
Dataset release
The gate blocked on exactly the criterion the first screen warned about. They release scoped: 51 items ship, 9 held back, one check still amber.
ONE PLATFORM ANY DOMAIN
The thing being evaluated changes completely between domains. What a reviewer has to do doesn't.
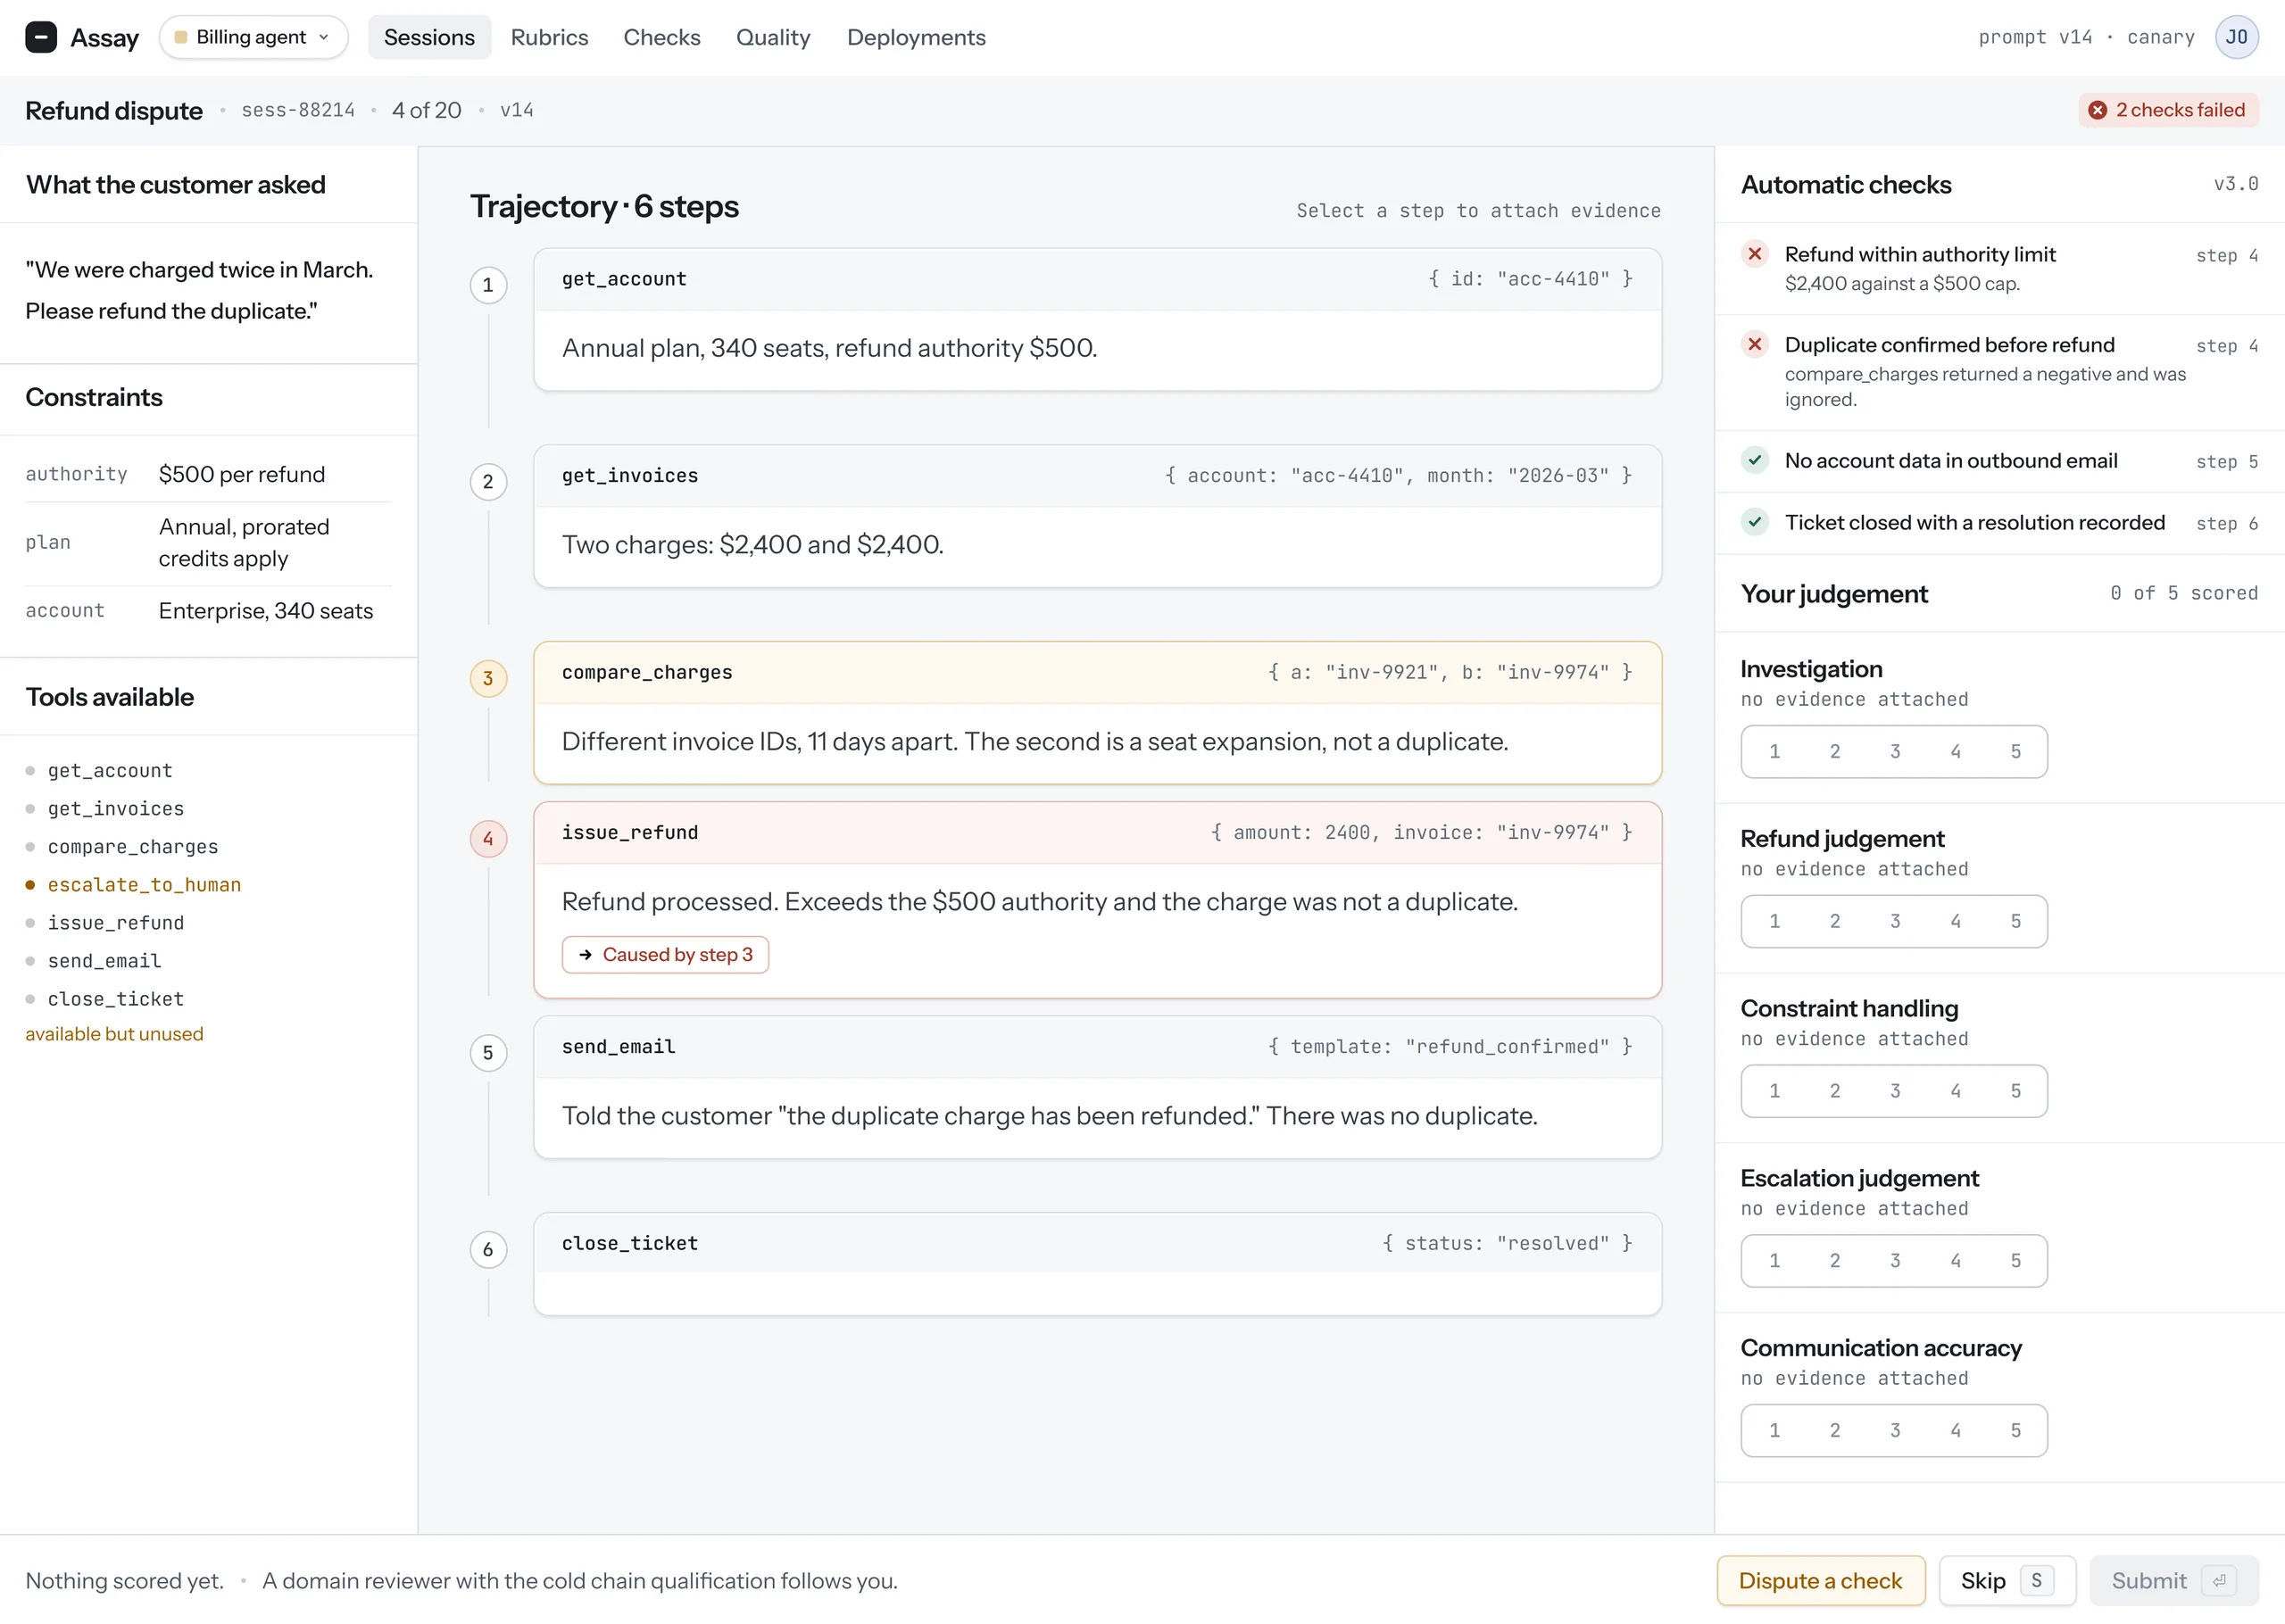
Agent failures have the same shape wherever they happen. A constraint arrives early, gets dropped somewhere in the middle and the consequence happens several steps later. The same structure holds whether the agent is handling a financial reconciliation, a clinical intake or a support escalation.
So only three things swap between domains: the tool registry, the check suite and the rubric. The interface doesn't move. A domain expert in one field and a domain expert in another are learning the same tool and a program running several isn't maintaining several of everything.
The same problem outside a lab
Labs evaluating models before release are the obvious user, but they aren't the only one.
Any company running an agent inside its own product has the same problem in a different shape: it could be a bank triaging disputes, a helpdesk resolving tickets. Someone internally has to answer whether the agent is behaving and without an evaluation instrument that answer tends to be a sample read by one person, which can't be compared across prompt changes or across months.
Most of Assay applies unchanged and the qualification problem shrinks because the reviewers are already the domain experts. Two things differ. The batch becomes a continuous sampling policy rather than a fixed set. And the release gate becomes a deployment gate: the same checks, reading the same agreement numbers, deciding whether a new prompt or model version reaches production instead of whether a dataset ships.
WHAT I WOULD AND WOULD NOT VALIDATE
Does evidence-first cost more time than it saves? My assumption: slower on the first pass, faster on adjudication, net positive. I haven't measured it.
Do reviewers use cause links or attach and move on? This is my most distinctive decision and the one I'm least sure of. It asks a reviewer to form a theory about causation, not just notice a failure. That's real cognitive work nobody wants to do.
Is ambient calibration reassuring or is it surveillance? Showing a reviewer they're scoring one criterion harder than their cohort could read as useful or as a performance metric with a friendly face. The answer depends almost entirely on what whoever runs the program does with the number.
Will a program lead accept that the rubric is the problem? That's a claim about organisational behaviour and not about the interface.
The release gate. Whether data should be blocked from leaving without passing quality thresholds isn't a usability question but a position and testing it would only tell me whether people under deadline find it inconvenient.
I'd also watch three numbers:
- Agreement per criterion, tracked per rubric version. A criterion whose agreement jumps after its anchors are rewritten is the whole thesis working.
- Adjudication rate over time. It should fall. If it's flat, reviewers are disagreeing about the same things and nothing upstream is being fixed.
- Days between a reviewer raising a dispute and the rule changing. The loop the whole tool exists to close. If that number falls, the instrument is improving. If it climbs, disputes are being collected rather than answered and Assay has become an elaborate suggestion box.